This article will show you how to get a random entry from a Dictionary in Python.
To make it more interesting, we have the following running scenario:
The Plot: Mr. Sinclair, an 8th great Science Teacher, is giving his students a quiz on the first 25 Periodic Table elements. He has asked you to write a Python script so that when run, it generates a random key, value, or key:value pair from the Dictionary shown below to ask his students.
The above code converts the Dictionary of Periodic Table Elements to a List of Tuples and saves it to el_list. If output to the terminal, the contents of el_list contains the following.
Before moving forward, please ensure the NumPy library is installed. Click here if you require instructions.
import numpy as np random_el = np.random.choice(list(els), 1)
print(random_el)
This code imports the NumPy library installed above.
Then, np.random.choice() is called and passed two (2) arguments: els converted to a List of Tuples and the number of random keys to return.
The results save to random_el and is output to the terminal.
['Chromium' 'Silicon' 'Oxygen']
Note: np.random.choice() has an additional parameter that can be passed. This parameter is a List containing associated probabilities.
Bonus:
This code generates a random key:value pair from a list of tuples. When the teacher runs this code, a random question displays on the screen and waits for a student to answer. Press 1 to display the answer, 2 to quit.
import keyboard
import random
import time els = {'Hydrogen': 'H', 'Helium': 'He', 'Lithium': 'Li', 'Beryllium': 'Be', 'Boron': 'B', 'Carbon': 'C', 'Nitrogen': 'N', 'Oxygen': 'O', 'Fluorine': 'F', 'Neon': 'Ne', 'Sodium': 'Na', 'Magnesium': 'Mg', 'Aluminum': 'Al', 'Silicon': 'Si', 'Phosphorus': 'P', 'Sulfur': 'S', 'Chlorine': 'Cl', 'Argon': 'Ar', 'Potassium': 'K', 'Calcium': 'Ca', 'Scandium': 'Sc', 'Titanium': 'Ti', 'Vanadium': 'V', 'Chromium': 'Cr', 'Manganese': 'Mn'} print('1 Answer 2 quit')
def quiz(): while True: k, v = random.choice(list(els.items())) print(f'\nWhat is the Symbol for {k}?') pressed = keyboard.read_key() if pressed == '1': print(f'The answer is {v}!') elif pressed == '2': print("Exiting\n") exit(0) time.sleep(5)
quiz()
Finxter Challenge! Write code to allow the teacher to enter the answer!
Summary
This article has provided five (5) ways to get a random entry from a Dictionary to select the best fit for your coding requirements.
Good Luck & Happy Coding!
Programmer Humor – Blockchain
“Blockchains are like grappling hooks, in that it’s extremely cool when you encounter a problem for which they’re the right solution, but it happens way too rarely in real life.”source – xkcd
The article begins by formulating a problem regarding how to extract emails from any website using Python, gives you an overview of solutions, and then goes into great detail about each solution for beginners.
At the end of this article, you will know the results of comparing methods of extracting emails from a website. Continue reading to find out the answers.
You may want to read out the disclaimer on web scraping here:
Statistics show that 33% of marketers send weekly emails, and 26% send emails multiple times per month. An email list is a fantastic tool for both company and job searching.
For instance, to find out about employment openings, you can hunt up an employee’s email address of your desired company.
However, manually locating, copying, and pasting emails into a CSV file takes time, costs money, and is prone to error. There are a lot of online tutorials for building email extraction bots.
When attempting to extract email from a website, these bots experience some difficulty. The issues include the lengthy data extraction times and the occurrence of unexpected errors.
Then, how can you obtain an email address from a company website in the most efficient manner? How can we use robust programming Python to extract data?
Method Summary
This post will provide two ways to extract emails from websites. They are referred to as Direct Email Extraction and Indirect Email Extraction, respectively.
Our Python code will search for emails on the target page of a given company or specific website when using the direct email extraction method.
For instance, when a user enters “www.scrapingbee.com” into their screen, our Python email extractor bot scrapes the website’s URLs. Then it uses a regex library to look for emails before saving them in a CSV file.
The second method, the indirect email extraction method, leverages Google.com’s Search Engine Result Page (SERP) to extract email addresses instead of using a specific website.
For instance, a user may type “scrapingbee.com” as the website name. The email extractor bot will search on this term and return the results to the system. The bot then stores the email addresses extracted using regex into a CSV file from these search results.
In the next section, you will learn more about these methods in more detail.
These two techniques are excellent email list-building tools.
The main issue with alternative email extraction techniques posted online, as was already said, is that they extract hundreds of irrelevant website URLs that don’t contain emails. The programming running through these approaches takes several hours.
Discover our two excellent methods by continuing reading.
Solution
Method 1 Direct Email Extraction
This method will outline the step-by-step process for obtaining an email address from a particular website.
Step 1: Install Libraries.
Using the pip command, install the following Python libraries:
import re
import requests
from bs4 import BeautifulSoup
from collections import deque
from urllib.parse import urlsplit
import pandas as pd
from tld import get_fld
Step 3: Create User Input.
Ask the user to enter the desired website for extracting emails with the input() function and store them in the variable user_url:
user_url = input("Enter the website url to extract emails: ")
if "https://" in user_url: user_url = user_url
else: user_url = "https://"+ user_url
Step 4: Set up variables.
Before we start writing the code, let’s define some variables.
Create two variables using the command below to store the URLs of scraped and un-scraped websites:
You can save the URLs of websites that are not scraped using the deque container. Additionally, the URLs of the sites that were scraped are saved in a set data format.
As seen below, the variable list_emails contains the retrieved emails:
list_emails = set()
Utilizing a set data type is primarily intended to eliminate duplicate emails and keep just unique emails.
Let us proceed to the next step of our main program to extract email from a website.
Step 5: Adding Urls for Content Extraction.
Web page URLs are transferred from the variable unscraped_url to scrapped_url to begin the process of extracting content from the user-entered URLs.
while len(unscraped_url): url = unscraped_url.popleft() scraped_url.add(url)
The popleft() method removes the web page URLs from the left side of the deque container and saves them in the url variable.
Then the url is stored in scraped_url using the add() method.
Step 6: Splitting of URLs and merging them with base URL.
The website contains relative links that you cannot access directly.
Therefore, we must merge the relative links with the base URL. We need the urlsplit() function to do this.
parts = urlsplit(url)
Create a parts variable to segment the URL as shown below.
Next, we create the basic URL by merging the scheme and netloc.
Base URL means the main website’s URL is what you type into the browser’s address bar when you input it.
If the user enters relative URLs when requested by the program, we must then convert them back to base URLs. We can accomplish this by using the command:
if '/' in parts.path: part = url.rfind("/") path = url[0:part + 1]
else: path = url
Let us understand how each line of the above command works.
This URL is a relative link, and the above set of commands will convert it to a base URL (https://www.scrapingbee.com). Let’s see how it works.
If the condition finds that there is a “/” in the path of the URL, then the command finds where is the last slash ”/” is located using the rfind() method. The “/” is located at the 27th position.
Next line of code stores the URL from 0 to 27 + 1, i.e., 28th item position, i.e., https://www.scrapingbee.com/. Thus, it converts to the base URL.
In the last command, If there is no relative link from the URL, it is the same as the base URL. That links are in the path variable.
The following command prints the URLs for which the program is scraping.
The regression is built to match the email address syntax displayed in the new emails variable. The regression format pulls the email address from the website URL’s content with the response.text method. And re.Iflag method ignores the font case. The list_emails set is updated with new emails.
The next is to find all of the website’s URL links and extract them in order to retrieve the email addresses that are currently available. You can utilize a powerful, beautiful soup module to carry out this procedure.
soup = BeautifulSoup(response.text, 'lxml')
A beautiful soup function parses the HTML document of the webpage the user has entered, as shown in the above command.
You can find out how many emails have been extracted with the following command.
Insert the command before the email regex command. Precisely, place this command above the new_emails variable.
Run the program now.
Did the program work?
Does it keep on running for several hours and not complete it?
The program searches and extracts all the URLs from the given website. Also, It is extracting links from other domain name websites. For example, the Scraping Bee website has URLs such as https://seekwell.io/., https://codesubmit.io/, and more.
A well-built website has up to 100 links for a single page of a website. So the program will take several hours to extract the links.
Sorry about it. You have to face this issue to get your target emails.
Bye Bye, the article ends here……..
No, I am just joking!
Fret Not! I will give you the best solution in the next step.
Step 8: Fix the code problems.
Here is the solution code for you:
if base_url in weblink: # code1 if ("contact" in weblink or "Contact" in weblink or "About" in weblink or "about" in weblink or 'CONTACT' in weblink or 'ABOUT' in weblink or 'contact-us' in weblink): #code2 if not weblink in unscraped_url and not weblink in scraped_url: unscraped_url.append(weblink)
First off, apply code 1, which specifies that you only include base URL websites from links weblinks to prevent scraping other domain name websites from a specific website.
Since the majority of emails are provided on the contact us and about web pages, only those links from those sites will be extracted (Refer to code 2). Other pages are not considered.
Finally, unscraped URLs are added to the unscrapped_url variable.
Step 9: Exporting the Email Address to CSV file.
Finally, we can save the email address in a CSV file (email2.csv) through data frame pandas.
url_name = "{0.netloc}".format(parts)
col = "List of Emails " + url_name
df = pd.DataFrame(list_emails, columns=[col])
s = get_fld(base_url)
df = df[df[col].str.contains(s) == True]
df.to_csv('email2.csv', index=False)
We use get_fld to save emails belonging to the first level domain name of the base URL. The s variable contains the first level domain of the base URL. For example, the first level domain is scrapingbee.com.
We include only emails ending with the website’s first-level domain name in the data frame. Other domain names that do not belong to the base URL are ignored. Finally, the data frame transfers emails to a CSV file.
As previously stated, a web admin can maintain up to 100 links per page.
Because there are more than 30 hyperlinks on each page for a normal website, it will still take some time to finish the program. If you believe that the software has extracted enough email, you may manually halt it using try except KeyboardInterrupt and raise SystemExit command as shown below:
try:
while len(unscraped_url):
… if base_url in weblink: if ("contact" in weblink or "Contact" in weblink or "About" in weblink or "about" in weblink or 'CONTACT' in weblink or 'ABOUT' in weblink or 'contact-us' in weblink): if not weblink in unscraped_url and not weblink in scraped_url: unscraped_url.append(weblink) url_name = "{0.netloc}".format(parts) col = "List of Emails " + url_name df = pd.DataFrame(list_emails, columns=[col]) s = get_fld(base_url) df = df[df[col].str.contains(s) == True] df.to_csv('email2.csv', index=False) except KeyboardInterrupt: url_name = "{0.netloc}".format(parts) col = "List of Emails " + url_name df = pd.DataFrame(list_emails, columns=[col]) s = get_fld(base_url) df = df[df[col].str.contains(s) == True] df.to_csv('email2.csv', index=False) print("Program terminated manually!") raise SystemExit
Run the program and enjoy it…
Let’s see what our fantastic email scraper application produced. The website I have entered is www.abbott.com.
Output:
Method 2 Indirect Email Extraction
You will learn the steps to extract email addresses from Google.com using the second method.
Step 1: Install Libraries.
Using the pip command, install the following Python libraries:
bs4 is a Beautiful soup for extracting google pages.
The pandas module can save emails in a DataFrame for future processing.
You can use Regular Expression (re) to match the Email Address format.
The request library sends HTTP requests.
You can use tld library to acquire relevant emails.
time library to delay the scraping of pages.
pip install bs4
pip install pandas
pip install re
pip install request
pip install time
Step 2: Import Libraries.
Import the libraries.
from bs4 import BeautifulSoup
import pandas as pd
import re
import requests
from tld import get_fld
import time
Step 3: Constructing Search Query.
The search query is written in the format “@websitename.com“.
Create an input for the user to enter the URL of the website.
The format of the search query is “@websitename.com,” as indicated in the code for the user_keyword variable above. The search query has opening and ending double quotes.
Step 4: Define Variables.
Before moving on to the heart of the program, let’s first set up the variables.
page = 0
list_email = set()
You can move through multiple Google search results pages using the page variable. And list_email for extracted emails set.
Step 5: Requesting Google Page.
In this step, you will learn how to create a Google URL link using a user keyword term and request the same.
The Main part of coding starts as below:
while page <= 100: print("Searching Emails in page No " + str(page)) time.sleep(20.00) google = "https://www.google.com/search?q=" + user_keyword + "&ei=dUoTY-i9L_2Cxc8P5aSU8AI&start=" + str(page) response = requests.get(google) print(response)
Let’s examine what each line of code does.
The while loop enables the email extraction bot to retrieve emails up to a specific number of pages, in this case 10 Pages.
The code prints the page number of the Google page being extracted. The first page is represented by page number 0, the second by page 10, the third by page 20, and so on.
To prevent having Google’s IP blocked, we slowed down the programming by 20 seconds and requested the URLs more slowly.
Before creating a google variable, let us learn more about the google search URL.
Suppose you search the keyword “Germany” on google.com. Then the Google search URL will be as follows
https://www.google.com/search?q=germany
If you click the second page of the Google search result, then the link will be as follows:
The user keyword is inserted after the “q=” symbol, and the page number is added after the “start=” as shown above in the google variable.
Request a Google webpage after that, then print the results. To test whether it’s functioning or not. The website was successfully accessed if you received a 200 response code. If you receive a 429, it implies that you have hit your request limit and must wait two hours before making any more requests.
Step 6: Extracting Email Address.
In this step, you will learn how to extract the email address from the google search result contents.
The Beautiful soup parses the web page and extracts the content of html web page.
With the regex findall() function, you can obtain email addresses, as shown above. Then the new email is updated to the list_email set. The page is added to 10 for navigating the next page.
n = len(user_keyword)-1
base_url = "https://www." + user_keyword[2:n]
col = "List of Emails " + user_keyword[2:n]
df = pd.DataFrame(list_email, columns=[col])
s = get_fld(base_url)
df = df[df[col].str.contains(s) == True]
df.to_csv('email3.csv', index=False)
And finally, target emails are saved to the CSV file from the above lines of code. The list item in the user_keyword starts from the 2nd position until the domain name.
Run the program and see the output.
Method 1 Vs. Method 2
Can we determine which approach is more effective for building an email list: Method 1 Direct Email Extraction or Method 2 Indirect Email Extraction? The output’s email list was generated from the website abbot.com.
Let’s contrast two email lists that were extracted using Methods 1 and 2.
From Method 1, the extractor has retrieved 60 emails.
From Method 2, the extractor has retrieved 19 emails.
The 17 email lists in Method 2 are not included in Method 1.
These emails are employee-specific rather than company-wide. Additionally, there are more employee emails in Method 1.
Thus, we are unable to recommend one procedure over another. Both techniques provide fresh email lists. As a result, both of these methods will increase your email list.
Summary
Building an email list is crucial for businesses and freelancers alike to increase sales and leads.
This article offers instructions on using Python to retrieve email addresses from websites.
The best two methods to obtain email addresses are provided in the article.
In order to provide a recommendation, the two techniques are finally compared.
The first approach is a direct email extractor from any website, and the second method is to extract email addresses using Google.com.
Regex Humor
Wait, forgot to escape a space. Wheeeeee[taptaptap]eeeeee. (source)
These examples use functions from the math library.
Add the following code to the top of each script. This snippet will allow the code in this article to run error-free.
import math
Method 1: Use a Generator Expression
This example uses a Generator Expression. This expression performs any operations in memory first and returns an iterable object. An efficient option as upon completion, memory is cleared, and variables erased.
nums = [18, 43, 54, 65, 31, 21, 27]
nums = (math.pow(num,2) for num in nums)
print(nums)
The above code declares a List of Integers and saves it to the variable nums.
Next, a Generator Expression is called and applies the math.pow() function from Python’s built-in math library to each list element. The results save back to nums.
If output to the terminal at this point, an iterable Generator Object similar to the following displays.
<generator object at 0x000002468D9B59A0>
To turn the Generator Object into a List, run the following code.
Note: The math.pow() function accepts two (2) integers as arguments: x (the value) and y (the power), and returns the value of x raised to the power of y.
nums = [18, 43, 54, 65, 31, 21, 27]
nums = [math.sqrt(num) for num in nums]
print(nums)
The above code declares a List of Integers and saves it to the variable nums.
Next, List Comprehension is called and applies themath.sqrt() function from Python’s built-in math library to each List element. The results save back to nums.
If output to the terminal, the following displays.
The above code declares a List of numbers and saves it to the variable nums.
Next, List is called and passed an argument map(), which in turn passes the lambda function to apply the math.degrees() function from Python’s built-in math library to each List element. The result returns to nums.
If output to the terminal, the following displays.
Note: The math.degrees() function accepts an angle as an argument, converts this argument from radians to degrees and returns the result.
Method 4: Use a For Loop
This example uses a for Loop to apply a mathematical operation to each List element.
nums = [18, 43, 54, 65, 31, 21, 27]
i = 0 while i < len(nums): nums[i] = round(math.sqrt(nums[i]), 2) i += 1 print(nums)
The above code declares a List of Integers and saves it to the variable nums. Then, a counter variable, i is declared, set to 0.
Next, a while loop is instantiated and iterates through each List element, applying the math.sqrt() function, and limiting the decimal places to two (2). The results save back to the appropriate element in nums.
Upon completion of the iteration, the output is sent to the terminal.
[4.24, 6.56, 7.35, 8.06, 5.57, 4.58, 5.2]
Bonus: Calculate Commissions on each List Element
This bonus code extracts two (2) columns from a real-estate.csv file, the street and price columns and converts each into a List.
Then, the street column is converted from UPPERCASEuppercase() to Title Case by applying the title() function. Next, Sales Commissions are calculated and applied to each price element using round().
import pandas as pd df = pd.read_csv('real-estate.csv', usecols=['street', 'price']).head(5) street = list(df['street'])
street = [item.title() for item in street] prices = list(df['price'])
commis = [round(p*.06,2) for p in prices] print(street)
print(prices)
Challenge: Given a Python list of strings and a query string. Find the strings that partially match the query string.
Example 1:
Input: ['hello', 'world', 'python'] and 'pyth'
Output: ['python']
Example 2:
Input: ['aaa', 'aa', 'a'] and 'a'
Output: ['aaa', 'aa', 'a']
Example 3:
Input: ['aaa', 'aa', 'a'] and 'b'
Output: []
Let’s dive into several methods that solve this and similar type of problems. We start with the most straightforward solution.
Method 1: Membership + List Comprehension
The most Pythonic way to find a list of partial matches of a given string query in a string list lst is to use the membership operator in and the list comprehension statement like so: [s for s in lst if query in s].
Here’s a simple example:
def partial(lst, query): return [s for s in lst if query in s] # Example 1:
print(partial(['hello', 'world', 'python'], 'pyth'))
# ['python'] # Example 2:
print(partial(['aaa', 'aa', 'a'], 'a'))
# ['aaa', 'aa', 'a'] # Example 3:
print(partial(['aaa', 'aa', 'a'], 'b'))
# []
In case you need some background information, feel free to check out our two tutorials and the referenced videos.
To find a list of partial query matches given a string list lst, combine the membership operator with the filter() function in which you pass a lambda function that evaluates the membership operation for each element in the list like so: list(filter(lambda x: query in x, lst)).
Here’s an example:
def partial(lst, query): return list(filter(lambda x: query in x, lst)) # Example 1:
print(partial(['hello', 'world', 'python'], 'pyth'))
# ['python'] # Example 2:
print(partial(['aaa', 'aa', 'a'], 'a'))
# ['aaa', 'aa', 'a'] # Example 3:
print(partial(['aaa', 'aa', 'a'], 'b'))
# []
Generally, I like list comprehension more than the filter() function because the former is more concise (e.g., no need to convert the result to a list) and slightly faster. But both work perfectly fine!
Method 3: Regex Match + List Comprehension
The most flexible way to find a list of partial query matches given a string list lst is provided by Python’s powerful regular expressions functionality. For example, the expression [x for x in lst if re.match(pattern, x)] finds all strings that match a certain query pattern as defined by you.
The following examples showcase this solution:
import re def partial(lst, query): pattern = '.*' + query + '.*' return [x for x in lst if re.match(pattern, x)] # Example 1:
print(partial(['hello', 'world', 'python'], 'pyth'))
# ['python'] # Example 2:
print(partial(['aaa', 'aa', 'a'], 'a'))
# ['aaa', 'aa', 'a'] # Example 3:
print(partial(['aaa', 'aa', 'a'], 'b'))
# []
In this example, we use the dummy pattern .*query.* that simply matches words that contain the query string. However, you could also do more advanced pattern matching—regex to the rescue!
Again, I’d recommend you check out the background info on regular expressions:
Given the following minimal example where you create a set and attempt to access an element of this set using indexing or slicing:
my_set = {1, 2, 3}
my_set[0]
If you run this code snippet, Python raises the TypeError: 'set' object is not subscriptable:
Traceback (most recent call last): File "C:\Users\xcent\Desktop\code.py", line 2, in <module> my_set[0]
TypeError: 'set' object is not subscriptable
Why Does the Error Occur?
The Python TypeError: 'set' object is not subscriptable occurs if you try to access an element of a set using indexing or slicing that imply an ordering of the set.
However, sets are unordered collections of unique elements: they have no ordering of elements. Thus, you cannot use slicing or indexing, operations that are only possible on an ordered type.
How to fix the TypeError: 'set' object is not subscriptable?
To fix the TypeError: 'set' object is not subscriptable, either convert the unordered set to an ordered list or tuple before accessing it or get rid of the indexing or slicing call altogether.
Here’s an example where you convert the unordered set to an ordered list first. Only then you use indexing or slicing so the error doesn’t occur anymore:
Here’s the code that applies these four steps, assuming the image is stored in a file named 'c++.jpg':
from PIL import Image
import numpy as np # 1. Read image
img = Image.open('c++.jpg') # 2. Convert image to NumPy array
arr = np.asarray(img)
print(arr.shape)
# (771, 771, 3) # 3. Convert 3D array to 2D list of lists
lst = []
for row in arr: tmp = [] for col in row: tmp.append(str(col)) lst.append(tmp) # 4. Save list of lists to CSV
with open('my_file.csv', 'w') as f: for row in lst: f.write(','.join(row) + '\n')
Note that the resulting CSV file looks like this with super long rows.
Each CSV cell (column) value is a representation of the RGB value at that specific pixel. For example, [255 255 255] represents the color white at that pixel.
For more information and some background on file I/O, check out our detailed tutorial on converting a list of lists to a CSV:
This article will show you how to find the most common element in a Python Dictionary. However, since all Dictionary Keys are unique, this article focuses on searching for the most common Dictionary Value.
To make it more fun, we have the following running scenario:
Marty Smart, a Math Teacher at Harwood High, has amassed his student’s grades for the semester and has come to you to write a script to determine the most common grade. Below is sample data.
Next, the counter() function is called and is passed all values from the key:value pair of students as an argument. Then, most_common() is appended. The results save to common_val.
If this was output to the terminal, the following would display.
[99, 76, 98, 99, 77, 98, 67, 61, 54, 76, 67, 99, 98, 49, 76, 99, 67, 54, 98, 100]
<built-in method count of list object at 0x00000239566D3540>
To retrieve the most common element, run the following code.
print(common_val)
99
Summary
This article has provided four (4) ways to find the most common element in a Python Dictionary. These examples should give you enough information to select the best fitting for your coding requirements.
Good Luck & Happy Coding!
Programmer Humor – Blockchain
“Blockchains are like grappling hooks, in that it’s extremely cool when you encounter a problem for which they’re the right solution, but it happens way too rarely in real life.”source – xkcd
We’ll first lay out the entire smart contract example without the comments for readability and development purposes.
Then we’ll dissect it part by part, analyze it and explain it.
Following this path, we’ll get a hands-on experience with smart contracts, as well as good practices in coding, understanding, and debugging smart contracts.
Parameters of the auction are variables beneficiary and auctionEndTime which we’ll initialize with contract creation arguments while the contract gets created, i.e. in the contract constructor.
Data type for time variables is unsigned integer uint, so that we can represent either absolute Unix timestamps (seconds since 1970-01-01) or time periods in seconds (seconds lapsed from the reference moment we chose).
address payable public beneficiary; uint public auctionEndTime;
The current state of the auction is reflected in two variables, highestBidder and highestBid.
address public highestBidder; uint public highestBid;
Previous bids can be withdrawn, that’s why we have mapping data structure to record pendingReturns.
mapping(address => uint) pendingReturns;
Indicator flag variable for the auction end. By default, the flag is initialized to false; we’ll prevent changing it once it switches to true.
bool ended;
When changes occur, we want our smart contract to emit the corresponding change events.
We’re defining four errors to describe relevant failures. Along with these errors, we’ll also introduce “triple-slash” comments, commonly known as natspec comments. They enable users to see comments when an error is displayed or when users are asked to confirm the transaction.
/// The auction has already ended. error AuctionAlreadyEnded(); /// There is already a higher or equal bid. error BidNotHighEnough(uint highestBid); /// The auction has not ended yet, the remaining seconds are displayed. error AuctionNotYetEnded(uint timeToAuctionEnd); /// The function auctionEnd has already been called. error AuctionEndAlreadyCalled();
Initialization of the contract with the contract creation arguments biddingTime and beneficiaryAddress.
/// Create a simple auction with `biddingTime` /// seconds bidding time on behalf of the /// beneficiary address `beneficiaryAddress`. constructor( uint biddingTime, address payable beneficiaryAddress ) { beneficiary = beneficiaryAddress; auctionEndTime = block.timestamp + biddingTime; }
A bidder bids by sending the currency (paying) to the smart contract representing the beneficiary, hence the bid() function is defined as payable.
/// Bid on the auction with the value sent /// together with this transaction. /// The value will only be refunded if the /// auction is not won. function bid() external payable {
The function call reverts if the bidding period ended.
if (block.timestamp > auctionEndTime) revert AuctionAlreadyEnded();
The function rolls back the transaction to the bidder if the bid does not exceed the highest one.
if (msg.value <= highestBid) revert BidNotHighEnough(highestBid);
The previous highest bidder was outbid and his bid is added to his previous bids reserved for a refund.
A direct refund is considered a security risk due to the possibility of executing an untrusted contract.
Instead, the bidders (recipients) will withdraw their bids themselves by using withdraw() function below.
if (highestBid != 0) { pendingReturns[highestBidder] += highestBid; }
The new highest bidder and his bid are recorded; the event HighestBidIncreased is emitted carrying this information pair.
Bidders call the withdraw() function to retrieve the amount they bid.
/// Withdraw a bid that was overbid. function withdraw() external returns (bool) { uint amount = pendingReturns[msg.sender]; if (amount > 0) {
It is possible to call the withdraw() function again before the send() function returns. That’s the reason why we need to disable multiple sequential withdrawals from the same sender by setting the pending returns for a sender to 0.
pendingReturns[msg.sender] = 0;
Variable type of msg.sender is not address payable, therefore we need to convert it explicitly by using function payable() as a wrapping function.
If the send() function ends with an error, we’ll just reset the pending amount and return false.
if (!payable(msg.sender).send(amount)) { // No need to call throw here, just reset the amount owing pendingReturns[msg.sender] = amount; return false; } } return true; }
The auctionEnd() function ends the auction and sends the highest bid to the beneficiary.
The official Solidity documentation recommends dividing the interacting functions into three functional parts:
checking the conditions,
performing the actions, and
interacting with other contracts.
Otherwise, by combining these parts rather than keeping them separated, more than one calling contract could try and modify the state of the called contract and change the called contract’s state.
/// End the auction and send the highest bid /// to the beneficiary. function auctionEnd() external {
Checking the conditions…
if (block.timestamp < auctionEndTime) revert AuctionNotYetEnded(auctionEndTime - block.timestamp); if (ended) revert AuctionEndAlreadyCalled();
Our smart contract example is a simple, but a powerful one, enabling us to bid an amount of currency to the beneficiary.
When the contract instantiates via its constructor, it sets the auction end time and its beneficiary, i.e. beneficiary address.
The contract has three simple features, implemented via dedicated functions: bidding, withdrawing the bids and ending the auction.
A new bid is accepted only if its amount is strictly larger than the current highest bid. A new bid acceptance means that the current highest bid is added to the bidder’s balance for later withdrawal. The new highest bidder becomes the current highest bidder and the new highest bid becomes the current highest bid.
Bid withdrawing returns all summed previous bids to each bidder (mapping pendingReturns).
Account 0x617F2E2fD72FD9D5503197092aC168c91465E7f2 withdraws his bids;
Appendix – The Contract Arguments
In this section is additional information for running the contract. We should expect that our example accounts may change with each refresh/reload of Remix.
Our contract creation arguments are the open auction duration (in seconds) and the beneficiary address (copy this line when deploying the example):
300, 0x5B38Da6a701c568545dCfcB03FcB875f56beddC4
Info: we could’ve used any amount of time, but I went with 300 seconds to timely simulate both a rejected attempt of ending the auction and the successful ending of the auction.
Conclusion
We continued our smart contract example series with this article that implements a simple open auction.
First, we laid out clean source code (without any comments) for readability purposes. Omitting the comments is not recommended, but we love living on the edge – and trying to be funny!
Second, we dissected the code, analyzed it, and explained each possibly non-trivial segment. Just because we’re terrific, safe players who never risk it and do everything by the book
Programmer Humor – Blockchain
“Blockchains are like grappling hooks, in that it’s extremely cool when you encounter a problem for which they’re the right solution, but it happens way too rarely in real life.”source – xkcd
The above code reads in the crimedescr column from the crimes.csv file downloaded earlier. This saves to the DataFrame df.
Next, the crimedescr column is then accessed, and the mode() method is appended. This method returns a value or set of values that appear most often along a selected axis. The results save to max_crime.
These results are output to the terminal.
0 10851(A)VC TAKE VEH W/O OWNER
Name: crimedescr, dtype: object
So, out of 7,854 rows of crimes committed on a given day for San Diego, the above offense was committed the highest number of times.
The above code only provides us with the name of the most common crime; what if we need the crime name and the respective count?
Now, you are equipped to return to your boss and tell them that 7,000 offenses of 10851 (A) VC TAKE VEH W/O OWNER occurred on a given day in San Diego.
Method 2: Use value_counts()
This example uses the value_counts() function to determine the top 5 most common crimes committed in San Diego on a given day.
The above code reads in the crimedescr and ucr_ncic_code columns from the crimes.csv file downloaded earlier. This saves to the DataFrame df.
Then, the crimedescr column is accessed, and the value_counts() function is appended. This function returns a series containing the counts of unique values.
However, since slicing is also appended ([:5]), only the top five (5) common crimes are retrieved and then converted to a List. The results save to top5_names.
['10851(A)VC TAKE VEH W/O OWNER', 'TOWED/STORED VEH-14602.6', '459 PC BURGLARY VEHICLE', 'TOWED/STORED VEHICLE', '459 PC BURGLARY RESIDENCE']
The above code only provides us with the names of the top 5 most common crimes; what if we need the names and their respective counts?
The above code reads in the crimedescr and ucr_ncic_code columns from the crimes.csv file downloaded earlier. This saves to the DataFrame df.
Then, the crimedescr column is accessed, and the value_counts() function is appended. This function returns a series containing the count of unique values.
Next, idxmax() is appended. This method returns the index of the first occurrence of the maximum index(es) over a selected axis.
The results save to max_crime and are output to the terminal.
10851(A)VC TAKE VEH W/O OWNER
Method 4: Use value_counts() and keys()
This example uses value_counts() and keys() to determine the top 5 most common crimes committed in unique grid areas of San Diego on a given day.
The above code reads in the crimedescr, grid, and the ucr_ncic_code columns from the crimes.csv file downloaded earlier. This saves to the DataFrame df.
Let’s break the highlighted line down.
If df['grid'].value_counts() was output to the terminal, the following would display (snippet). However, we have added a heading row to make it more understandable, and only five (5) rows are displayed.
Grid #
Grid Total
742
115
969
105
958
100
564
80
1084
71
Next, the code keys()[:5] is appended. The final output displays as follows.
The above code reads in the crimedescr and the ucr_ncic_code columns from the crimes.csv file downloaded earlier. This saves to the DataFrame df.
Next, the groupby() function is called and passed the first argument: df.groupby(['ucr_ncic_code','crimedescr']).size(). If this was output to the terminal at this point, the following would display (snippet).
As you can see, the other arguments need to be added to turn this into something usable. Sorting the data in descending order and adding a count column will provide the results we are looking for.
If the original Method 5 code example was output to the terminal, the following would display.
ucr_ncic_code
crimedescr
count
0
2404
10851(A)VC TAKE VEH W/O OWNER
653
1
7000
TOWED/STORED VEH-14602.6
463
2
2299
459 PC BURGLARY VEHICLE
462
3
7000
TOWED/STORED VEHICLE
434
4
2204
459 PC BURGLARY RESIDENCE
356
Summary
This article has provided five (5) ways to find the most common element in a Panda Column. These examples should provide you with enough information to select the one that best meets your coding requirements.
Good Luck & Happy Coding!
Programming Humor – Python
“I wrote 20 short programs in Python yesterday. It was wonderful. Perl, I’m leaving you.” — xkcd
You’re not alone! This short tutorial will show you why this error occurs, how to fix it, and how to never make the same mistake again.
So, let’s get started!
Summary
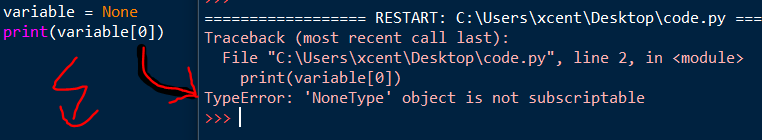
Python raises the TypeError: NoneType is not subscriptable if you try to index x[i] or slice x[i:j] a None value. The None type is not indexable, i.e., it doesn’t define the __getitem__() method. You can fix it by removing the indexing or slicing call, or defining the __getitem__ method.
Example
The following minimal example that leads to the error:
x = None
print(x[0])
# TypeError: 'NoneType' object is not subscriptable
You set the variable to the value None. The value None is not a container object, it doesn’t contain other objects. So, the code really doesn’t make any sense—which result do you expect from the indexing operation?
Exercise: Before I show you how to fix it, try to resolve the error yourself in the following interactive shell:
If you struggle with indexing in Python, have a look at the following articles on the Finxter blog—especially the third!
You overwrite the __getitem__ method that takes one (index) argument i (in addition to the obligatory self argument) and returns the i-th value of the “container”.
In our case, we just return a string "Value 0" for the element variable[0] and "Value 10" for the element variable[10].
I hope you’d be able to fix the bug in your code! Before you go, check out our free Python cheat sheets that’ll teach you the basics in Python in minimal time:

 The Plot: Mr. Sinclair, an 8th great Science Teacher, is giving his students a quiz on the first 25 Periodic Table elements. He has asked you to write a Python script so that when run, it generates a random key, value, or key:value pair from the Dictionary shown below to ask his students.
 Question: How would we write code to get a random entry from a Dictionary?


 Note:
 Finxter Challenge!

 Recommended Tutorial:

 In the next section, you will learn more about these methods in more detail.




 Finxter Challenge!


 Recommended Tutorial: