Amazon Black Friday Anime Sale Has Great Deals On Blu-Rays, Box Sets, And More
Black Friday has kicked off, and if you're looking to spend the end of the year with some quality animation directly from Japan, Amazon's got a terrific selection of Blu-rays and box sets at great prices. The Black Friday sale includes a number of cult classic series such as Cowboy Bebop (currently in development as a live-action series for Netflix), Black Lagoon, and Naruto Shippuden.
More modern series are also included in the Black Friday sale, like the violent fantasy epic Goblin Slayer, the twisted superhero series Zetman, and the wonderfully weird Jojo's Bizarre Adventure.
Posted by: xSicKxBot - 11-28-2020, 02:44 AM - Forum: Python
- No Replies
Exponential Fit with SciPy’s curve_fit()
In this article, you’ll explore how to generate exponential fits by exploiting the curve_fit() function from the Scipy library. SciPy’s curve_fit() allows building custom fit functions with which we can describe data points that follow an exponential trend.
In the first part of the article, the curve_fit() function is used to fit the exponential trend of the number of COVID-19 cases registered in California (CA).
The second part of the article deals with fitting histograms, characterized, also in this case, by an exponential trend.
Disclaimer: I’m not a virologist, I suppose that the fitting of a viral infection is defined by more complicated and accurate models; however, the only aim of this article is to show how to apply an exponential fit to model (to a certain degree of approximation) the increase in the total infection cases from the COVID-19.
Exponential fit of COVID-19 total cases in California
Data related to the COVID-19 pandemic have been obtained from the official website of the “Centers for Disease Control and Prevention” (https://data.cdc.gov/Case-Surveillance/United-States-COVID-19-Cases-and-Deaths-by-State-o/9mfq-cb36) and downloaded as a .csv file. The first thing to do is to import the data into a Pandas dataframe. To do this, the Pandas functions pandas.read_csv() and pandas.Dataframe() were employed. The created dataframe is made up of 15 columns, among which we can find the submission_date, the state, the total cases, the confirmed cases and other related observables. To gain an insight into the order in which these categories are displayed, we print the header of the dataframe; as can be noticed, the total cases are listed under the voice “tot_cases”.
Since in this article we are only interested in the data related to the California, we create a sub-dataframe that contains only the information related to the California state. To do that, we exploit the potential of Pandas in indexing subsections of a dataframe. This dataframe will be called df_CA (from California) and contains all the elements of the main dataframe for which the column “state” is equal to “CA”. After this step, we can build two arrays, one (called tot_cases) that contains the total cases (the name of the respective header column is “tot_cases”) and one that contains the number of days passed by the first recording (called days). Since the data were recorded daily, in order to build the “days” array, we simply build an array of equally spaced integer number from 0 to the length of the “tot_cases” array, in this way, each number refers to the n° of days passed from the first recording (day 0).
At this point, we can define the function that will be used by curve_fit()to fit the created dataset. An exponential function is defined by the equation:
y = a*exp(b*x) +c
where a, b and c are the fitting parameters. We will hence define the function exp_fit() which return the exponential function, y, previously defined. The curve_fit() function takes as necessary input the fitting function that we want to fit the data with, the x and y arrays in which are stored the values of the datapoints. It is also possible to provide initial guesses for each of the fitting parameters by inserting them in a list called p0 = […] and upper and lower boundaries for these parameters (for a comprehensive description of the curve_fit() function, please refer to https://docs.scipy.org/doc/scipy/reference/generated/scipy.optimize.curve_fit.html ). In this example, we will only provide initial guesses for our fitting parameters. Moreover, we will only fit the total cases of the first 200 days; this is because for the successive days, the number of cases didn’t follow an exponential trend anymore (possibly due to a decrease in the number of new cases). To refer only to the first 200 values of the arrays “days” and “tot_cases”, we exploit array slicing (e.g. days[:200]).
The output of curve_fit() are the fitting parameters, presented in the same order that was used during their definition, within the fitting function. Keeping this in mind, we can build the array that contains the fitted results, calling it “fit_eq”.
Now that we built the fitting array, we can plot both the original data points and their exponential fit.
The final result will be a plot like the one in Figure 1:
Figure 1
Application of an exponential fit to histograms
Now that we know how to define and use an exponential fit, we will see how to apply it to the data displayed on a histogram. Histograms are frequently used to display the distributions of specific quantities like prices, heights etc…The most common type of distribution is the Gaussian distribution; however, some types of observables can be defined by a decaying exponential distribution. In a decaying exponential distribution, the frequency of the observables decreases following an exponential[A1] trend; a possible example is the amount of time that the battery of your car will last (i.e. the probability of having a battery lasting for long periods decreases exponentially). The exponentially decaying array will be defined by exploiting the Numpy function random.exponential(). According to the Numpy documentation, the random.exponential() function draws samples from an exponential distribution; it takes two inputs, the “scale” which is a parameter defining the exponential decay and the “size” which is the length of the array that will be generated. Once obtained random values from an exponential distribution, we have to generate the histogram; to do this, we employ another Numpy function, called histogram(), which generates an histogram taking as input the distribution of the data (we set the binning to “auto”, in this way the width of the bins is automatically computed). The output of histogram() is a 2D array; the first array contains the frequencies of the distribution while the second one contains the edges of the bins. Since we are only interested in the frequencies, we assign the first output to the variable “hist”. For this example, we will generate the array containing the bin position by using the Numpy arange() function; the bins will have a width of 1 and their number will be equal to the number of elements contained in the “hist” array.
At this point, we have to define the fitting function and to call curve_fit() for the values of the just created histogram. The equation describing an exponential decay is similar to the one defined in the first part; the only difference is that the exponent has a negative sign, this allows the values to decrease according to an exponential fashion. Since the elements in the “x” array, defined for the bin position, are the coordinates of the left edge of each bin, we define another x array that stores the position of the center of each bin (called “x_fit”); this allows the fitting curve to pass through the center of each bin, leading to a better visual impression. This array will be defined by taking the values of the left side of the bins (“x” array elements) and adding half the bin size; which corresponds to half the value of the second bin position (element of index 1). Similar to the previous part, we now call curve_fit(), generate the fitting array and assign it to the varaible “fit_eq”.
Once the distribution has been fitted, the last thing to do is to check the result by plotting both the histogram and the fitting function. In order to plot the histogram, we will use the matplotlib function bar(), while the fitting function will be plotted using the classical plot() function.
The final result is displayed in Figure 2:
Figure 2
Summary
In these two examples, the curve_fit()function was used to apply to different exponential fits to specific data points. However, the power of the curve_fit()function, is that it allows you defining your own custom fit functions, being them linear, polynomial or logarithmic functions. The procedure is identical to the one shown in this article, the only difference is in the shape of the function that you have to define before calling curve_fit().
Full Code
import pandas as pd

import numpy as np

import matplotlib.pyplot as plt

from scipy.optimize import curve_fit url = "United_States_COVID-19_Cases_and_Deaths_by_State_over_Time" #url of the .csv file

file = pd.read_csv(url, sep = ';', thousands = ',') # import the .csv file

df = pd.DataFrame(file) # build up the pandas dataframe

print(df.columns) #visualize the header

df_CA = df[df['state'] == 'CA'] #initialize a sub-dataframe for storing only the values for the California

tot_cases = np.array((df_CA['tot_cases'])) #create an array with the total n° of cases

days = np.linspace(0, len(tot_cases), len(tot_cases)) # array containing the n° of days from the first recording #DEFINITION OF THE FITTING FUNCTION

def exp_fit(x, a, b, c): y = a*np.exp(b*x) + c return y #----CALL THE FITTING FUNCTION----

fit = curve_fit(exp_fit,days[:200],tot_cases[:200], p0 = [0.005, 0.03, 5])

fit_eq = fit[0][0]*np.exp(fit[0][1]*days[:200])+fit[0][2] # #----PLOTTING-------

fig = plt.figure()

ax = fig.subplots()

ax.scatter(days[:200], tot_cases[:200], color = 'b', s = 5)

ax.plot(days[:200], fit_eq, color = 'r', alpha = 0.7)

ax.set_ylabel('Total cases')

ax.set_xlabel('N° of days')

plt.show() #-----APPLY AN EXPONENTIAL FIT TO A HISTOGRAM--------

data = np.random.exponential(5, size=10000) #generating a random exponential distribution

hist = np.histogram(data, bins="auto")[0] #generating a histogram from the exponential distribution

x = np.arange(0, len(hist), 1) # generating an array that contains the coordinated of the left edge of each bar #---DECAYING FIT OF THE DISTRIBUTION----

def exp_fit(x,a,b): #defining a decaying exponential function y = a*np.exp(-b*x) return y x_fit = x + x[1]/2 # the point of the fit will be positioned at the center of the bins

fit_ = curve_fit(exp_fit,x_fit,hist) # calling the fit function

fit_eq = fit_[0][0]*np.exp(-fit_[0][1]*x_fit) # building the y-array of the fit

#Plotting

plt.bar(x,hist, alpha = 0.5, align = 'edge', width = 1)

plt.plot(x_fit,fit_eq, color = 'red')

plt.show()
[www.indiegala.com] F1® 2020 is putting players firmly in the driving seat as they race against the best drivers in the world. Don't miss a historical low price!
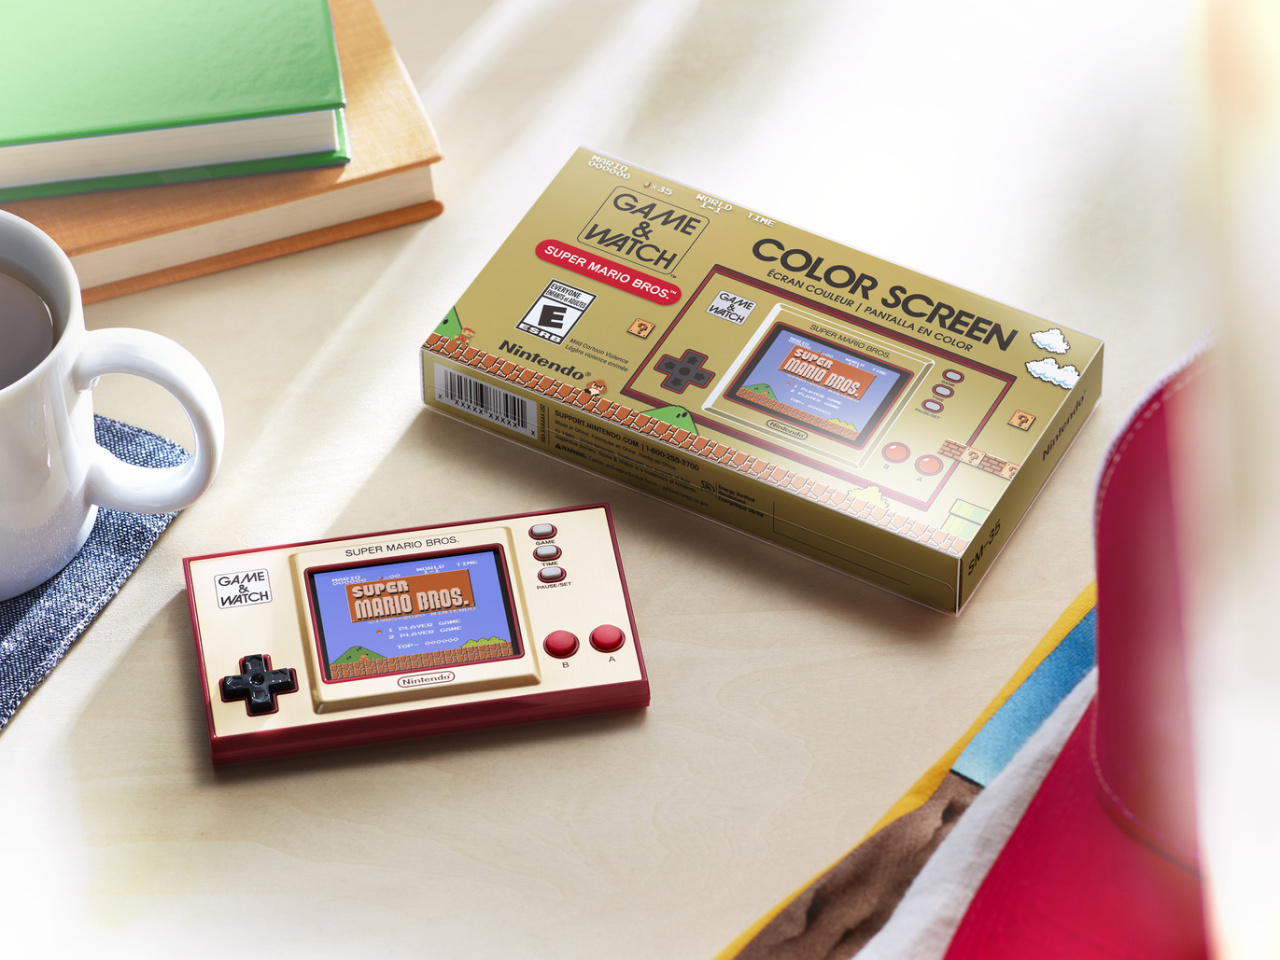
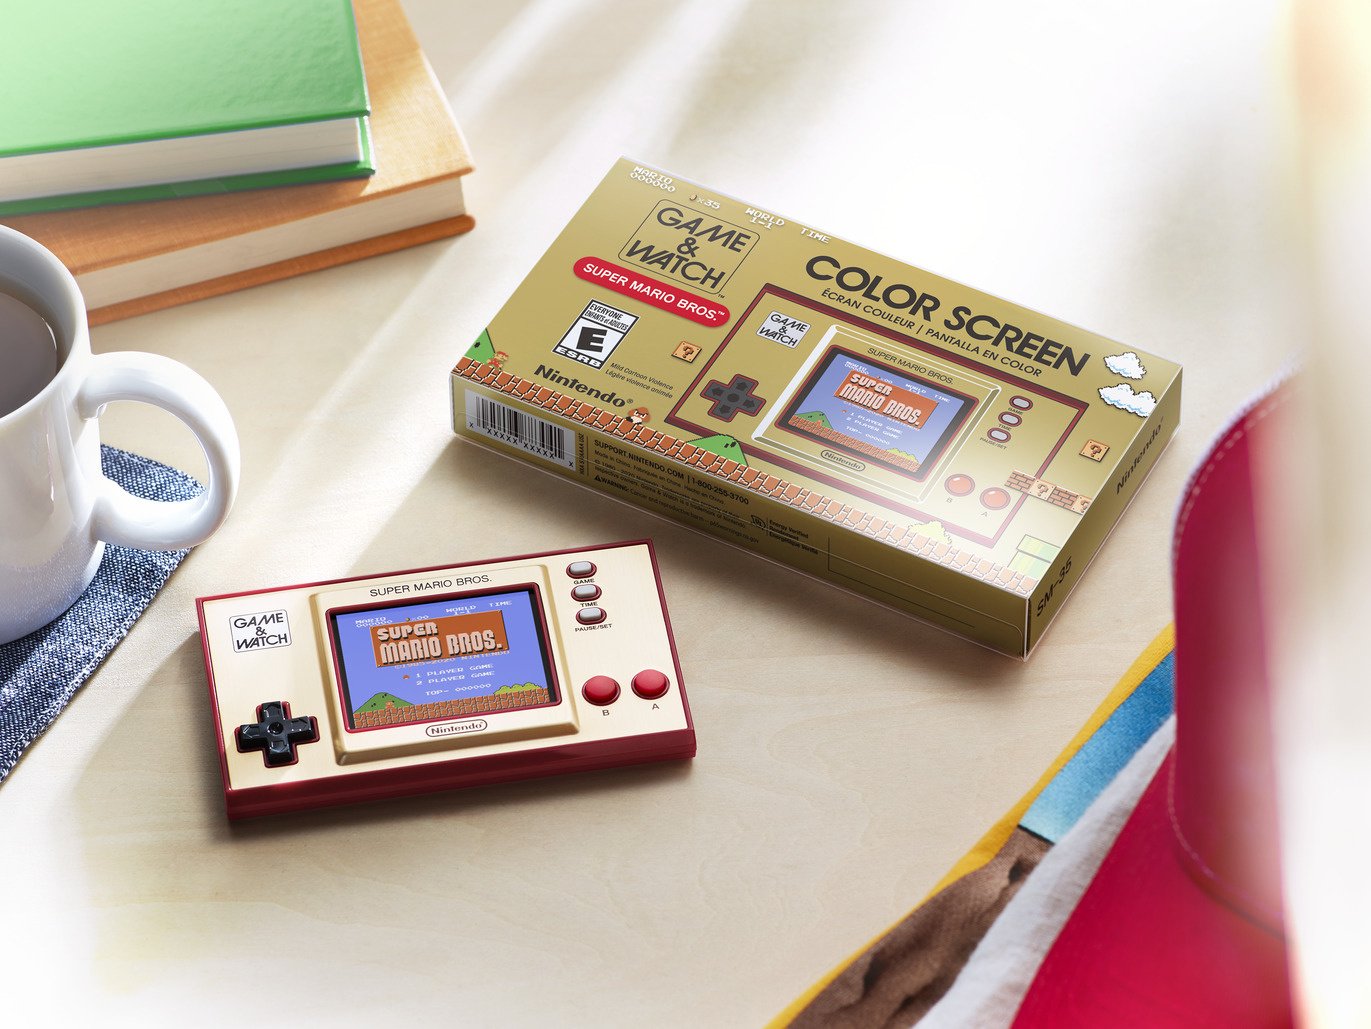
Guide: Where To Buy Game & Watch: Super Mario Bros.
Update 27th Nov 2020: Unsurprisingly, stock for the Game & Watch has been in short supply. But Nintendo Official UK Store is now taking pre-orders which will be despatched on 18th December. Just in time for Santa to put in your Xmas stocking!
Much like the NES and SNES Mini before it, the dinky Game & Watch: Super Mario Bros. is sure to be a collector’s item and hard to get your hands on in the future. Naughty scalpers are sure to have a field day with this one!
Game & Watch: Super Mario Bros. arrives in stores on November 13th and it includes the following retro-tastic Mario games (and a clock!):
Please note that some external links on this page are affiliate links, which means if you click them and make a purchase we may receive a small percentage of the sale. Please read our FTC Disclosure for more information.
Buy Game & Watch Super Mario Bros. In The UK
At the time of writing, UK readers have their pick of places to order from. The official Nintendo Store UK has the unit £5 cheaper than the competition, except for ShopTo which shaves fourteen pennies off Nintendo’s price and is currently the best deal available.
Buy Game & Watch Super Mario Bros. In The US
Stock has been impossible to pre-order in the US, although some stores are now starting to show the Game & Watch as being in-stock and ready to add to your cart. The following product pages are now live, so keep trying and good luck!
Import Game & Watch Super Mario Bros.
On the import front, stock is sold out at the official Nintendo site in Japan and Play Asia, too. The official Nintendo option only ships to residents of Japan anyway, but with Play Asia apparently sold out of its allocation, it looks like US residents will have to sit tight for the time being.
We’re keeping on the lookout for more G&W Super Mario Bros. pre-orders, so watch this space!
Posted by: xSicKxBot - 11-28-2020, 02:43 AM - Forum: Lounge
- No Replies
Sega Genesis Mini Gets Black Friday Price Drop At Amazon
Black Friday has no shortage of current-gen game deals, but if you're craving a retro gaming experience, the Sega Genesis Mini is a great option. Loaded with 42 games, it's currently available for $50 at Amazon during the store's Black Friday sale. This isn't the lowest price we've ever seen it at, but it's still a solid purchase if you want to relive the classic Sega games of your childhood. The Sega Genesis Mini comes preloaded with 42 iconic games, such as Sonic the Hedgehog and Castlevania: Bloodlines, and it also includes two wired controllers--everything you need comes in the box.
Every year here on GameFromScratch we gather all of the relevant game development related Black Friday and Cyber Monday deals and 2020 is no exception. What follows is a list of the best deals we have found for game developers, be it programmers, musicians or artists. It will be updated as additional deals are discovered so be sure to check back. Links below may contain an affiliate code that pays GFS a small commission if you make a purchase.
A collection of 700+ Assets 50% off as well as an asset of the day 70% off. Additionally Unity Pro and Unity Enterprise licenses come with a free gift up to $1600 value.
This one runs until the end of the year, get audio plugins and premium memberships at a 25% discount, with higher discounts the more items you purchase.
Lots of gear, computers etc on sale, free shipping.
Amazon
You Know… It’s Amazon
You can learn more about the above sales in the video below. Leave a comment on the video or the GFS discord if you spot another deal you want to share with your fellow game developers and I will add it to the list.
This has been called the age of DevOps, and operating systems seem to be getting a little bit less attention than tools are. However, this doesn’t mean that there has been no innovation in operating systems. [Edit: The diversity of offerings from the plethora of distributions based on the Linux kernel is a fine example of this.] Fedora CoreOS has a specific philosophy of what an operating system should be in this age of DevOps.
Fedora CoreOS’ philosophy
Fedora CoreOS (FCOS) came from the merging of CoreOS Container Linux and Fedora Atomic Host. It is a minimal and monolithic OS focused on running containerized applications. Security being a first class citizen, FCOS provides automatic updates and comes with SELinux hardening.
For automatic updates to work well they need to be very robust. The goal being that servers running FCOS won’t break after an update. This is achieved by using different release streams (stable, testing and next). Each stream is released every 2 weeks and content is promoted from one stream to the other (next -> testing -> stable). That way updates landing in the stable stream have had the opportunity to be tested over a long period of time.
Getting Started
For this example let’s use the stable stream and a QEMU base image that we can run as a virtual machine. You can use coreos-installer to download that image.
From your (Workstation) terminal, run the following commands after updating the link to the image. [Edit: On Silverblue the container based coreos tools are the simplest method to try. Instructions can be found at https://docs.fedoraproject.org/en-US/fedora-coreos/tutorial-setup/ , in particular “Setup with Podman or Docker”.]
To customize a FCOS system, you need to provide a configuration file that will be used by Ignition to provision the system. You may use this file to configure things like creating a user, adding a trusted SSH key, enabling systemd services, and more.
The following configuration creates a ‘core’ user and adds an SSH key to the authorized_keys file. It is also creating a systemd service that uses podman to run a simple hello world container.
version: "1.0.0"

variant: fcos

passwd: users: - name: core ssh_authorized_keys: - ssh-ed25519 my_public_ssh_key_hash fcos_key

systemd: units: - contents: | [Unit] Description=Run a hello world web service After=network-online.target Wants=network-online.target [Service] ExecStart=/bin/podman run --pull=always --name=hello --net=host -p 8080:8080 quay.io/cverna/hello ExecStop=/bin/podman rm -f hello [Install] WantedBy=multi-user.target enabled: true name: hello.service
After adding your SSH key in the configuration save it as config.yaml. Next use the Fedora CoreOS Config Transpiler (fcct) tool to convert this YAML configuration into a valid Ignition configuration (JSON format).
Install fcct directly from Fedora’s repositories or get the binary from GitHub.
Once the installation is successful, some information is displayed and a login prompt is provided.
Fedora CoreOS 32.20200907.3.0

Kernel 5.8.10-200.fc32.x86_64 on an x86_64 (ttyS0)

SSH host key: SHA256:BJYN7AQZrwKZ7ZF8fWSI9YRhI++KMyeJeDVOE6rQ27U (ED25519)

SSH host key: SHA256:W3wfZp7EGkLuM3z4cy1ZJSMFLntYyW1kqAqKkxyuZrE (ECDSA)

SSH host key: SHA256:gb7/4Qo5aYhEjgoDZbrm8t1D0msgGYsQ0xhW5BAuZz0 (RSA)

ens2: 192.168.122.237 fe80::5054:ff:fef7:1a73

Ignition: user provided config was applied

Ignition: wrote ssh authorized keys file for user: core
The Ignition configuration file did not provide any password for the core user, therefore it is not possible to login directly via the console. (Though, it is possible to configure a password for users via Ignition configuration.)
Use Ctrl + ] key combination to exit the virtual machine’s console. Then check if the hello.service is running.
Using the preconfigured SSH key, you can also access the VM and inspect the services running on it.
$ ssh core@192.168.122.237

$ systemctl status hello

● hello.service - Run a hello world web service

Loaded: loaded (/etc/systemd/system/hello.service; enabled; vendor preset: enabled)

Active: active (running) since Wed 2020-10-28 10:10:26 UTC; 42s ago
zincati, rpm-ostree and automatic updates
The zincati service drives rpm-ostreed with automatic updates. Check which version of Fedora CoreOS is currently running on the VM, and check if Zincati has found an update.
$ ssh core@192.168.122.237

$ rpm-ostree status

State: idle

Deployments:

● ostree://fedora:fedora/x86_64/coreos/stable

Version: 32.20200907.3.0 (2020-09-23T08:16:31Z)

Commit: b53de8b03134c5e6b683b5ea471888e9e1b193781794f01b9ed5865b57f35d57

GPGSignature: Valid signature by 97A1AE57C3A2372CCA3A4ABA6C13026D12C944D0

$ systemctl status zincati

● zincati.service - Zincati Update Agent

Loaded: loaded (/usr/lib/systemd/system/zincati.service; enabled; vendor preset: enabled)

Active: active (running) since Wed 2020-10-28 13:36:23 UTC; 7s ago

…

Oct 28 13:36:24 cosa-devsh zincati[1013]: [INFO ] initialization complete, auto-updates logic enabled

Oct 28 13:36:25 cosa-devsh zincati[1013]: [INFO ] target release '32.20201004.3.0' selected, proceeding to stage it ... zincati reboot ...
After the restart, let’s remote login once more to check the new version of Fedora CoreOS.
rpm-ostree status now shows 2 versions of Fedora CoreOS, the one that came in the QEMU image, and the latest one received from the update. By having these 2 versions available, it is possible to rollback to the previous version using the rpm-ostree rollback command.
Finally, you can make sure that the hello service is still running and serving content.
Fedora CoreOS provides a solid and secure operating system tailored to run applications in containers. It excels in a DevOps environment which encourages the hosts to be provisioned using declarative configuration files. Automatic updates and the ability to rollback to a previous version of the OS, bring a peace of mind during the operation of a service.
Learn more about Fedora CoreOS by following the tutorials available in the project’s documentation.
PQube Is Releasing A Totally Free “DanMachi” Shmup On The Switch eShop
Is It Wrong To Try To Pick Up Girls In A Dungeon? – Infinite Combate has to rank as one of the silliest names for a video game ever, but the RPG – which is based on Danjon ni Deai o Motomeru no wa Machigatteiru Darō ka, or ‘DanMachi’ as it’s more commonly known amongst fans – is still a good pick for ardent followers of the genre.
When it was originally released in Japan, a shmup based on the game – entitled Is It Wrong To Try To Shoot ’em Up Girls In A Dungeon? – was offered as pre-order DLC, but western publisher PQube has confirmed that it is releasing that very same game for free on the eShop – and you don’t even have to own the main game to access it.
Is It Wrong To Try To Shoot ’em Up Girls In A Dungeon? was supposed to go live earlier this week, but PQube has noted that there have been some issues in making it available on the eShop:
Here’s some PR:
Take control of Aiz Wallenstein, Loki Familia’s first-class swordswoman, and fight through hordes of enemies in this shoot’em up side-scroller based on DanMachi (Is it Wrong to Try to Pick Up Girls in a Dungeon?).
Aiz has powerful “wind shots.”
Choose from a total of five support characters from the story and utilize their diverse shooting styles to complete the dungeon! You start off with just Tiona and Lefiya, and you unlock the other three once you’ve cleared the game.
Collect power-ups that appear as you defeat enemies to gain power-ups, from speed to more lives, and get the best possible score!
The game has four stages, each with a boss, so get ready to change tactics and blast them away before trying again!
There are four difficulty levels, Easy, Normal, Hard and Death, giving a chance for beginners and experienced shooters alike to enjoy this free shoot’em up!
Fortnite and esports team 100 Thieves have come together to create an in-game version of the 100 Thieves Cash App Compound.
100 Thieves x @FortniteGame Welcome to the 100 Thieves Cash App Compound… in Fortnite! Packed with quests & easter eggs, our Compound is now fully explorable in Fortnite Creative. Drop into the Creative Hub now!@FNCreate | #100TCreativepic.twitter.com/OaZFrRUmTD
Located in Fortnite Creative's Welcome Hub, the Compound offers players four themed quests tied to 100 Thieves' members, including Nadeshot, CouRage, Valkyrae, and BrookeAB. Upon completion, players can explore new areas of the Compound and find other surprises.
Fortnite and 100 Thieves will also hold a contest and fans can participate for a chance to get a VIP Fortnite swag bag, merch from the 100 Thieves Jam Collection line, and more. Fans can enter the contest by taking a screenshot or video recording their favorite Fortnite character in the in-game 100 Thieves Compound. Then they'll need to upload the content on social media and tag the post with #100TCreative, as well as the handles @100Thieves and @FNCreate. Participants need to submit their post by December 1.
Pokémon Teases ‘Very Special’ 25th Anniversary Celebrations For 2021
The Pokémon Company International has teased upcoming celebrations surrounding the series’ 25th anniversary next year.
The tease began with a special Pokémon brand performance during the annual Macy’s Thanksgiving Day Parade today, where a troupe of Pikachu danced to the original Pokémon theme song in New York’s Herald Square.
Following the performance, the company posted a teasing tweet and shared the following statement in a press release:
The Pokémon Company International invites fans around the world to stay tuned for more information about the very special upcoming celebration of Pokémon’s 25th anniversary in 2021.
Looks like 2021 could be a big year for Pokémon fans. What would you like to see? New games? Remakes? Other projects? Share all below.