



07-01-2022, 12:41 PM
pd.agg() – Aggregating Data in Pandas
5/5 – (1 vote)
The name agg is short for aggregate. To aggregate is to summarize many observations into a single value that represents a certain aspect of the observed data.
The function can process a dataframe, a series, or a grouped dataframe. It can execute many aggregation functions, e.g. ‘’, ‘’,… in a single call along one of the axis. It can also execute lambda functions. Read on for examples.
We will use a dataset of FIFA players. Find the dataset here.
Basic Setup using Jupyter Notebook
Let’s start by importing pandas and loading our dataset.

To increase readability, we will work with a subset of the data. Let’s create the subset by selecting the columns we want to have in our subset and create a new dataframe.

Basic Aggregation
Pandas provides a variety of built-in aggregation functions. For example,. When applied to a dataset, it returns a summary of statistical values.

To understand aggregation and why it is helpful, let’s have a closer look at the data returned.
Example: Our dataset contains records for 17954 players. The youngest player is 17 years of age and the oldest player is 46 years old. The mean age is 25 years. We learn that the tallest player is 205 cm tall and the average player’s height is around 175 cm. With a single line of code, we can answer a variety of statistical questions about our data. The function identifies numeric columns and performs the statistical aggregation for us. Describe also excluded the column that contains string values.
To aggregate is to summarize many observations into a single value that represents a certain aspect of the observed data.
Pandas provides us with a variety of pre-built aggregate functions.
Functions |
Description
|
returns the mean of a set of values
|
returns the sum of a set of values
|
returns the count of a set of values
|
returns the standard deviation of a set of values
|
returns the smallest value of a set of values
|
returns the largest value of a set of values
|
returns a collection of statistical values of a set of values
|
returns the size of a set of values
|
returns the first value of a set of values
|
returns the last value of a set of values
|
returns the nth value of a set of values
|
returns the standard error of the mean of a set of value
|
returns the variance of a set of values
|
returns the count of unique values of a set of values
Let’s use another function from the list above. We can be more specific and request the ‘’ for the ‘’ series. This column contains the market value of a player. We select the column or series ‘’ and execute the pre-build function.
Pandas returned us the requested value. Let’s get to know an even more powerful pandas method for aggregating data.
The ‘pandas.DataFrame.agg’ Method
Function Syntax
The function can take in many input types. The output type is, to a large extent, determined by the input type. We can pass in many parameters to the function.
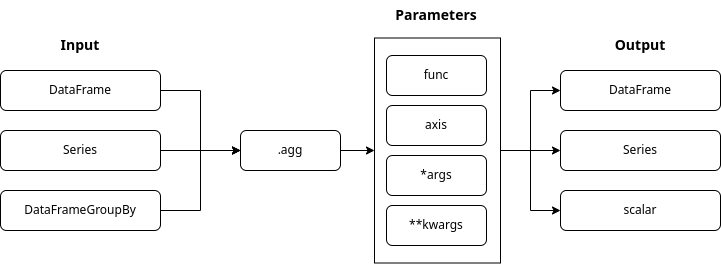
The “” parameter:
The “” parameter:
What about and :
Agg method on a Series
Let’s see the function in action. We request some of the pre-build aggregation functions for the ‘’ series. We use the function parameter and provide the aggregate functions we want to execute as a list. And let’s save the resulting series in a variable.

Pandas uses scientific notation for large and small floating-point numbers. To convert the output to a familiar format, we must move the floating point to the right as shown by the plus sign. The number behind the plus sign represents the amount of steps.
Let’s do this together for some values.
The sum of all wages is 175,347,000€ (1.753470e+08)
The mean of the wages is 9902.135€ (9.902135e+03)
We executed many functions on a series input source. Thus our variable ‘’ is of the type because.
See below how to extract, for example, the ‘’ value from the variable and the data type returned.
The data type is now a scalar.
If we execute a single function on the same data source (series), the type returned is a scalar.
Let’s use one more example to understand the relation between the input type and the output type.
We will use the function “” which will give us the count of unique nationalities. Let’s apply the function in two code examples. We will reference the series ‘’ both times. The only difference will be the way we pass the function “” into our function.
When we use a dictionary to pass in the “” function, the output type is a series.
When we pass the “” function directly into the output type is an integer.
Agg method on a DataFrame
Passing the aggregation functions as a Python list
One column represents a series. We will now select two columns as our input and so work with a dataframe.
Let’s select the columns ‘’ and ‘’.
We will execute the functions, and . To select a two-dimensional data (dataframe), we need to use double brackets. We will round the results to two decimal points.
Let’s store the result in a variable.

We get a data frame containing rows and columns. Let’s confirm this observation by checking the type of the ‘’ variable.
We will now use our newly created dataframe named ‘’ to use the ‘’ parameter. The entire dataframe contains numeric values.
We define the functions and pass in the parameter. I used the and functions to show the effect of the parameter. The resulting values make little sense. This is also the reason why I do not rename the headings to restore the lost column names.

We aggregated along the rows. Returning the count of items and the sum of item values in each row.
Passing the aggregation functions as a python dictionary
Now let’s apply different functions to the individual sets in our dataframe. We select the sets ‘’ and ‘’. We will apply the functions , and to the ‘’ series, and the functions and to the ‘’ series.

The dataframe contains calculated and empty (NaN) values. Let’s quickly confirm the type of our output.
Passing the aggregation functions as a Python tuple
We will now repeat the previous example.
We will use tuples instead of a dictionary to pass in the aggregation functions. Tuple have limitations. We can only pass one aggregation function within a tuple. We also have to name each tuple.

Agg method on a grouped DataFrame
Grouping by a single column
The ‘’ method creates a grouped dataframe. We will now select the columns ‘’ and ‘’ and group our dataframe using the column ‘’. On our grouped dataframe we will apply the function using the functions , , and .

Every row represents an age group. The count value shows how many players fall into the age group. The min, max and mean values aggregate the data of the age-group members.
Multiindex
One additional aspect of a grouped dataframe is the resulting hierarchical index. We also call it multiindex.
We can see that the individual columns of our grouped dataframe are at different levels. Another way to view the hierarchy is to request the columns for the particular dataset.

Working with a multiindex is a topic for another blog post. To use the tools that we have discussed, let’s flatten the multiindex and reset the index. We need the following functions:

The resulting dataframe columns are now flat. We lost some information during the flattening process. Let’s rename the columns and return some of the lost context.

Grouping by multiple columns
Grouping by multiple columns creates even more granular subsections.
Let’s use ‘’ as the first grouping parameter and ‘’ as the second. We will aggregate the resulting group data using the columns ‘’ and ‘’. We are by now familiar with the aggregation functions used in this example.

Every age group contains nationality groups. The aggregated athletes data is within the nationality groups.
Custom aggregation functions
We can write and execute custom aggregation functions to answer very specific questions.
Let’s have a look at the inline lambda functions.
 Lambda functions are so-called anonymous functions. They are called this way because they do not have a name. Within a lambda function, we can execute multiple expressions. We will go through several examples to see lambda functions in action.
In pandas lambda functions live inside the “” and the “” methods. We will use the method to execute functions along both axes. Let’s have a look at the basics first.
Function Syntax
The function will execute a function along defined axes of a DataFrame. The functions that we will execute in our examples will work with Series objects passed into our custom functions by the method. Depending on the axes that we will select, the Series will comprise out of a row or a column or our data frame.

The “” parameter:
The “” parameter:
The “” parameter:
The “” parameter:
The “” parameter:
The parameter:
Filters
Let’s have a look at filters. They will be very handy as we explore our data.
In this code example, we create a filter named. We select our dataframe and the column . The condition returns if the value in the column is 90 or above.
Otherwise, the filter returns.

The result is a Series object containing the index, and the correlated value of or .
Let’s apply the filter to our dataframe. We call the method and pass in the filter’s name as a list item. The filter works like a mask. It covers all rows that have the value . The remaining rows match our filter criteria of .

Lambda functions
Let’s recreate the same filter using a lambda function. We will call our filter.
Let’s go over the code. We specify the name of our filter and call our dataframe. Pay attention to the double square brackets. We use them to pass a dataframe and not a Series object to the method.
Inside we use the keyword ‘’ to show that we are about to define our anonymous function. The ‘’ represents the Series passed into the lambda function.
The series contains the data from the column. After the semicolumn, we use the placeholder again. Now we apply a method called . It represents the same condition we used in our first filter example “” (greater or equal).
We define the integer value 90 and close the brackets on our apply function. The result is a dataframe that contains an index and only one column of boolean values. To convert this dataframe to a Series we use the method.
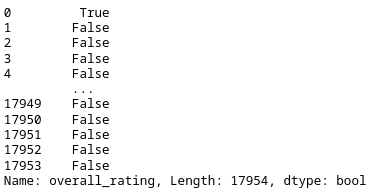
Let’s use our filter. Great, we get the same result as in our first filter example.

We now want to know how many players our filter returned. Let’s first do it without a lambda function and then use a lambda function to see the same result. We are counting the lines or records.


Great. Now let’s put us in a place where we actually need to use the method and a lambda function. We want to use our filter on a grouped data-frame.
Let’s group by nationality to see the distribution of these amazing players. The output will contain all columns. This makes the code easier to read.

Pandas tells us in this error message that we can not use the ‘’ method on a grouped dataframe object.
Let’s now see how we can solve this problem by using a lambda function. Instead of using the ‘’ function on the grouped dataframe we use the function. Inside the function we define our lambda function. Now we use the ‘’ method on the variable ‘’ and pass our filter.

Axis parameter of the apply() function
Now let’s use the parameter to calculate the Body-Mass-Index (BMI) for these players. Until now we have used the lambda functions on the columns of our data.
The ‘’ variable was a representation of the individual column. We set the axis parameter to ‘’. The ‘’ variable in our lambda function will now represent the individual rows of our data.
Before we calculate the BMI let’s create a new dataframe and define some columns. We will call our new dataframe ‘’.

Now let’s reset the index.

We calculate the BMI as follows. We divide the weight in kilogram by the square of the height in meters.
Let’s have a closer look at the lambda function. We define the ‘’ to be ‘’. The ‘’ variable now represents a row. We need to use specific values in each row. To define these values, we use the variable ‘’ and specify a column name. At the beginning of our code example, we define a new column named ‘’. And at the very end, we round the results.
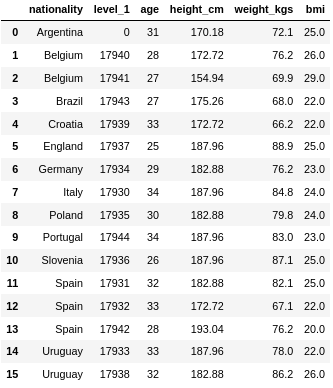
Great! Our custom function worked. The new BMI column contains calculated values.
Conclusion
Congratulations on finishing the tutorial. I wish you many great and small insights for your future data projects. I include the Jupyter-Notebook file, so you can experiment and tweak the code.
Nerd Humor
 [i]Oh yeah, I didn’t even know they renamed it the Willis Tower in 2009, because I know a normal amount about skyscrapers. — xkcd (source)[/i]
5/5 – (1 vote)
The name agg is short for aggregate. To aggregate is to summarize many observations into a single value that represents a certain aspect of the observed data.
The
Code:
.agg()Code:
meanCode:
maxWe will use a dataset of FIFA players. Find the dataset here.
Basic Setup using Jupyter Notebook
Let’s start by importing pandas and loading our dataset.
Code:
import pandas as pd
df_fifa_soccer_players = pd.read_csv('fifa_cleaned.csv')
df_fifa_soccer_players.head()
To increase readability, we will work with a subset of the data. Let’s create the subset by selecting the columns we want to have in our subset and create a new dataframe.
Code:
df_fifa_soccer_players_subset = df_fifa_soccer_players[['nationality', 'age', 'height_cm', 'weight_kgs', 'overall_rating', 'value_euro', 'wage_euro']]
df_fifa_soccer_players_subset.head()
Basic Aggregation
Pandas provides a variety of built-in aggregation functions. For example,
Code:
pandas.DataFrame.describeCode:
df_fifa_soccer_players_subset.describe()To understand aggregation and why it is helpful, let’s have a closer look at the data returned.
Example: Our dataset contains records for 17954 players. The youngest player is 17 years of age and the oldest player is 46 years old. The mean age is 25 years. We learn that the tallest player is 205 cm tall and the average player’s height is around 175 cm. With a single line of code, we can answer a variety of statistical questions about our data. The
Code:
describeCode:
nationalityTo aggregate is to summarize many observations into a single value that represents a certain aspect of the observed data.
Pandas provides us with a variety of pre-built aggregate functions.
Functions |
Description
Code:
mean()returns the mean of a set of values
Code:
sum()returns the sum of a set of values
Code:
count()returns the count of a set of values
Code:
std()returns the standard deviation of a set of values
Code:
min()returns the smallest value of a set of values
Code:
max()returns the largest value of a set of values
Code:
describe()returns a collection of statistical values of a set of values
Code:
size()returns the size of a set of values
Code:
first()returns the first value of a set of values
Code:
last()returns the last value of a set of values
Code:
nth()returns the nth value of a set of values
Code:
sem()returns the standard error of the mean of a set of value
Code:
var()returns the variance of a set of values
Code:
nunique()returns the count of unique values of a set of values
Let’s use another function from the list above. We can be more specific and request the ‘
Code:
sumCode:
value_euroCode:
value_euroCode:
sum()Code:
df_fifa_soccer_players_subset['value_euro'].sum()
# 43880780000.0
Pandas returned us the requested value. Let’s get to know an even more powerful pandas method for aggregating data.
The ‘pandas.DataFrame.agg’ Method
Function Syntax
The
Code:
.agg()Code:
.agg()The “
Code:
func- is by default set to Code:
None
- contains one or many functions that aggregate the data
- supports pre-defined pandas aggregate functions
- supports lambda expressions
- supports the method for specific function callsCode:
dataframe.apply()
The “
Code:
axis- is by default set to 0 and applies functions to each column
- if set to 1 applies functions to rows
- can hold values:
- or ‘’Code:
index
- or ‘Code:
1’Code:columns
- or ‘
What about
Code:
*argsCode:
**kwargs- we use these placeholders, if we do not know in advance how many arguments we will need to pass into the function
- when arguments are of the same type, we use Code:
*args
- When arguments are of different types, we use .Code:
**kwargs
Agg method on a Series
Let’s see the
Code:
.agg()Code:
wage_euroCode:
wage_stats = df_fifa_soccer_players_subset['wage_euro'].agg(['sum', 'min', 'mean', 'std', 'max'])
print(wage_stats)
Pandas uses scientific notation for large and small floating-point numbers. To convert the output to a familiar format, we must move the floating point to the right as shown by the plus sign. The number behind the plus sign represents the amount of steps.
Let’s do this together for some values.
The sum of all wages is 175,347,000€ (1.753470e+08)
The mean of the wages is 9902.135€ (9.902135e+03)
We executed many functions on a series input source. Thus our variable ‘
Code:
wage_statsCode:
SeriesCode:
type(wage_stats)
# pandas.core.series.Series
See below how to extract, for example, the ‘
Code:
minCode:
wage_stats_min = wage_stats['min']
print(wage_stats_min)
# 1000.0 print(type(wage_stats_min))
# numpy.float64
The data type is now a scalar.
If we execute a single function on the same data source (series), the type returned is a scalar.
Code:
wage_stats_max = df_fifa_soccer_players_subset['wage_euro'].agg('max')
print(wage_stats_max)
# 565000.0 print(type(wage_stats_max))
# numpy.float64
Let’s use one more example to understand the relation between the input type and the output type.
We will use the function “
Code:
nuniqueCode:
nationalityCode:
nuniqueCode:
agg()Code:
nationality_unique_series = df_fifa_soccer_players_subset['nationality'].agg({'nationality':'nunique'})
print(nationality_unique_series)
# nationality 160
# Name: nationality, dtype: int64 print(type(nationality_unique_series))
# pandas.core.series.Series
When we use a dictionary to pass in the “
Code:
nuniqueCode:
nationality_unique_int = df_fifa_soccer_players_subset['nationality'].agg('nunique')
print(nationality_unique_int)
# 160 print(type(nationality_unique_int))
# int
When we pass the “
Code:
nuniqueCode:
agg()Agg method on a DataFrame
Passing the aggregation functions as a Python list
One column represents a series. We will now select two columns as our input and so work with a dataframe.
Let’s select the columns ‘
Code:
height_cmCode:
weight_kgsWe will execute the functions
Code:
min()Code:
mean()Code:
max()Let’s store the result in a variable.
Code:
height_weight = df_fifa_soccer_players_subset[['height_cm', 'weight_kgs']].agg(['min', 'mean', 'max']).round(2)
print(height_weight)
We get a data frame containing rows and columns. Let’s confirm this observation by checking the type of the ‘
Code:
height_weightCode:
print(type(height_weight))
# pandas.core.frame.DataFrame
We will now use our newly created dataframe named ‘
Code:
height_weightCode:
axisWe define the functions and pass in the
Code:
axisCode:
count()Code:
sum()Code:
axisCode:
height_weight.agg(['count', 'sum'], axis=1)We aggregated along the rows. Returning the count of items and the sum of item values in each row.
Passing the aggregation functions as a python dictionary
Now let’s apply different functions to the individual sets in our dataframe. We select the sets ‘
Code:
overall_ratingCode:
value_euroCode:
std()Code:
sem()Code:
mean()Code:
overall_ratingCode:
min()Code:
max()Code:
value_euroCode:
rating_value_euro_dict = df_fifa_soccer_players_subset[['overall_rating', 'value_euro']].agg({'overall_rating':['std', 'sem', 'mean'], 'value_euro':['min', 'max']})
print(rating_value_euro_dict)
The dataframe contains calculated and empty (NaN) values. Let’s quickly confirm the type of our output.
Code:
print(type(rating_value_euro_dict))
# pandas.core.frame.DataFrameWe will now repeat the previous example.
We will use tuples instead of a dictionary to pass in the aggregation functions. Tuple have limitations. We can only pass one aggregation function within a tuple. We also have to name each tuple.
Code:
rating_value_euro_tuple = df_fifa_soccer_players_subset[['overall_rating', 'value_euro']].agg(overall_r_std=('overall_rating', 'std'),overall_r_sem=('overall_rating', 'sem'),overall_r_mean=('overall_rating', 'mean'),value_e_min=('value_euro', 'min'),value_e_max=('value_euro', 'max'))
print(rating_value_euro_tuple)
Agg method on a grouped DataFrame
Grouping by a single column
The ‘
Code:
groupbyCode:
ageCode:
wage_euroCode:
ageCode:
agg()Code:
count()Code:
min()Code:
max()Code:
mean()Code:
age_group_wage_euro = df_fifa_soccer_players_subset[['age', 'wage_euro']].groupby('age').aggage(['count', 'min', 'max', 'mean'])
print(age_group_wage_euro)
Every row represents an age group. The count value shows how many players fall into the age group. The min, max and mean values aggregate the data of the age-group members.
Multiindex
One additional aspect of a grouped dataframe is the resulting hierarchical index. We also call it multiindex.
We can see that the individual columns of our grouped dataframe are at different levels. Another way to view the hierarchy is to request the columns for the particular dataset.
Code:
print(age_group_wage_euro.columns)Working with a multiindex is a topic for another blog post. To use the tools that we have discussed, let’s flatten the multiindex and reset the index. We need the following functions:
- Code:
droplevel()
- Code:
reset_index()
Code:
age_group_wage_euro_flat = age_group_wage_euro.droplevel(axis=1, level=0).reset_index()
print(age_group_wage_euro_flat.head())
The resulting dataframe columns are now flat. We lost some information during the flattening process. Let’s rename the columns and return some of the lost context.
Code:
age_group_wage_euro_flat.columns = ['age', 'athlete_count', 'min_wage_euro', 'max_wage_euro', 'mean_wage_euro']
print(age_group_wage_euro_flat.head())
Grouping by multiple columns
Grouping by multiple columns creates even more granular subsections.
Let’s use ‘
Code:
ageCode:
nationalityCode:
overall_ratingCode:
height_cmCode:
df_fifa_soccer_players_subset.groupby(['age', 'nationality']).agg({'overall_rating':['count', 'min', 'max', 'mean'], 'height_cm':['min', 'max', 'mean']})Every age group contains nationality groups. The aggregated athletes data is within the nationality groups.
Custom aggregation functions
We can write and execute custom aggregation functions to answer very specific questions.
Let’s have a look at the inline lambda functions.
Lambda functions are so-called anonymous functions. They are called this way because they do not have a name. Within a lambda function, we can execute multiple expressions. We will go through several examples to see lambda functions in action.In pandas lambda functions live inside the “
Code:
DataFrame.apply()Code:
Series.appy()Code:
DataFrame.appy()Function Syntax
The
Code:
DataFrame.apply()Code:
apply()The “
Code:
func- contains a function applied to a column or a row of the data frame
The “
Code:
axis- is by default set to 0 and will pass a series of column data
- if set to 1 will pass a series of the row data
- can hold values:
- 0 or ‘’Code:
index
- 1 or ‘’Code:
columns
- 0 or ‘
The “
Code:
raw- is a boolean value
- is by default set to Code:
False
- can hold values:
- -> a Series object is passed to the functionCode:
False
- -> aCode:
Trueobject is passed to the functionCode:ndarray
The “
Code:
result_type- can only apply when the axis is 1 or ‘’Code:
columns
- can hold values:
- ‘’Code:
expand
- Code:
‘reduce’
- ‘’Code:
broadcast
- ‘
The “
Code:
args()- additional parameters for the function as tuple
The
Code:
**kwargs- additional parameters for the function as key-value pairs
Filters
Let’s have a look at filters. They will be very handy as we explore our data.
In this code example, we create a filter named
Code:
filt_ratingCode:
overall_ratingCode:
>= 90Code:
TrueCode:
overall_ratingOtherwise, the filter returns
Code:
FalseCode:
filt_rating = df_fifa_soccer_players_subset['overall_rating'] >= 90
print(filt_rating)
The result is a Series object containing the index, and the correlated value of
Code:
TrueCode:
FalseLet’s apply the filter to our dataframe. We call the
Code:
.locCode:
FalseCode:
overall_rating >= 90Code:
df_fifa_soccer_players_subset.loc[filt_rating]Lambda functions
Let’s recreate the same filter using a lambda function. We will call our filter
Code:
filt_rating_lambdaLet’s go over the code. We specify the name of our filter and call our dataframe. Pay attention to the double square brackets. We use them to pass a dataframe and not a Series object to the
Code:
.appy()Inside
Code:
.apply()Code:
lambdaCode:
xThe series contains the data from the
Code:
overall_ratingCode:
xCode:
ge()Code:
>=We define the integer value 90 and close the brackets on our apply function. The result is a dataframe that contains an index and only one column of boolean values. To convert this dataframe to a Series we use the
Code:
squeeze()Code:
filt_rating_lambda = df_fifa_soccer_players_subset[['overall_rating']].apply(lambda x:x.ge(90)).squeeze()
print(filt_rating_lambda)
Let’s use our filter. Great, we get the same result as in our first filter example.
Code:
df_fifa_soccer_players_subset.loc[filt_rating_lambda]We now want to know how many players our filter returned. Let’s first do it without a lambda function and then use a lambda function to see the same result. We are counting the lines or records.
Code:
df_fifa_soccer_players_subset.loc[filt_rating_lambda].count()Code:
df_fifa_soccer_players_subset.apply(lambda x:x.loc[filt_rating_lambda]).count()Great. Now let’s put us in a place where we actually need to use the
Code:
apply()Let’s group by nationality to see the distribution of these amazing players. The output will contain all columns. This makes the code easier to read.
Code:
df_fifa_soccer_players_subset.groupby('nationality').loc[filt_rating_lambda]Pandas tells us in this error message that we can not use the ‘
Code:
locLet’s now see how we can solve this problem by using a lambda function. Instead of using the ‘
Code:
locCode:
apply()Code:
apply()Code:
locCode:
xCode:
df_fifa_soccer_players_subset.groupby('nationality').apply(lambda x:x.loc[filt_rating_lambda])Axis parameter of the apply() function
Now let’s use the
Code:
axisThe ‘
Code:
xCode:
1Code:
xBefore we calculate the BMI let’s create a new dataframe and define some columns. We will call our new dataframe ‘
Code:
df_bmiCode:
df_bmi = df_fifa_soccer_players_subset.groupby('nationality')[['age', 'height_cm', 'weight_kgs']].apply(lambda x:x.loc[filt_rating_lambda])
print(df_bmi)
Now let’s reset the index.
Code:
df_bmi = df_bmi.reset_index()
print(df_bmi)
We calculate the BMI as follows. We divide the weight in kilogram by the square of the height in meters.
Let’s have a closer look at the lambda function. We define the ‘
Code:
axisCode:
1Code:
xCode:
xCode:
bmiCode:
df_bmi['bmi'] = df_bmi.apply(lambda x:x['weight_kgs']/((x['height_cm']/100)**2), axis=1).round()
print(df_bmi)
Great! Our custom function worked. The new BMI column contains calculated values.
Conclusion
Congratulations on finishing the tutorial. I wish you many great and small insights for your future data projects. I include the Jupyter-Notebook file, so you can experiment and tweak the code.
Nerd Humor
[i]Oh yeah, I didn’t even know they renamed it the Willis Tower in 2009, because I know a normal amount about skyscrapers. — xkcd (source)[/i]