



12-12-2020, 09:42 AM
Pandas apply() — A Helpful Illustrated Guide

The Pandas function is used to apply the functions on the Pandasobjects. We have so many built-in aggregation functions in pandas on Series and DataFrame objects. But, to apply some application-specific functions, we can leverage the function. Pandas is both the Series method and DataFrame method.
Pandas apply function to one column – apply( ) as Series method
Let’s construct a DataFrame in which we have the information of 4 persons.
takes any of the below two different kinds of functions as an argument. They are:
1. Python functions
In Python, there are 3 different kinds of functions in general;
a) Applying Python built-in functions on Series
If we would like to know the length of the names of each person, we can do so using the function in python.
For example, if we want to know the length of the “Python” string, we can get by the following code;
A single column in the DataFrame is a Series object. Now, we would like to apply the same function on the whole “Name” column of the DataFrame. This can be achieved using the function in the below code;
If you observe the above code snippet, the inside the function is not taking any argument. In general, any function takes some data to operate on them. In the code snippet, it’s taking the string as input data to calculate its length. Here, the input data is directly taken from the Series object that called the function using .
When applying the Python functions, each value in the Series is applied one by one and returns the Series object.
The above process can be visualised as:
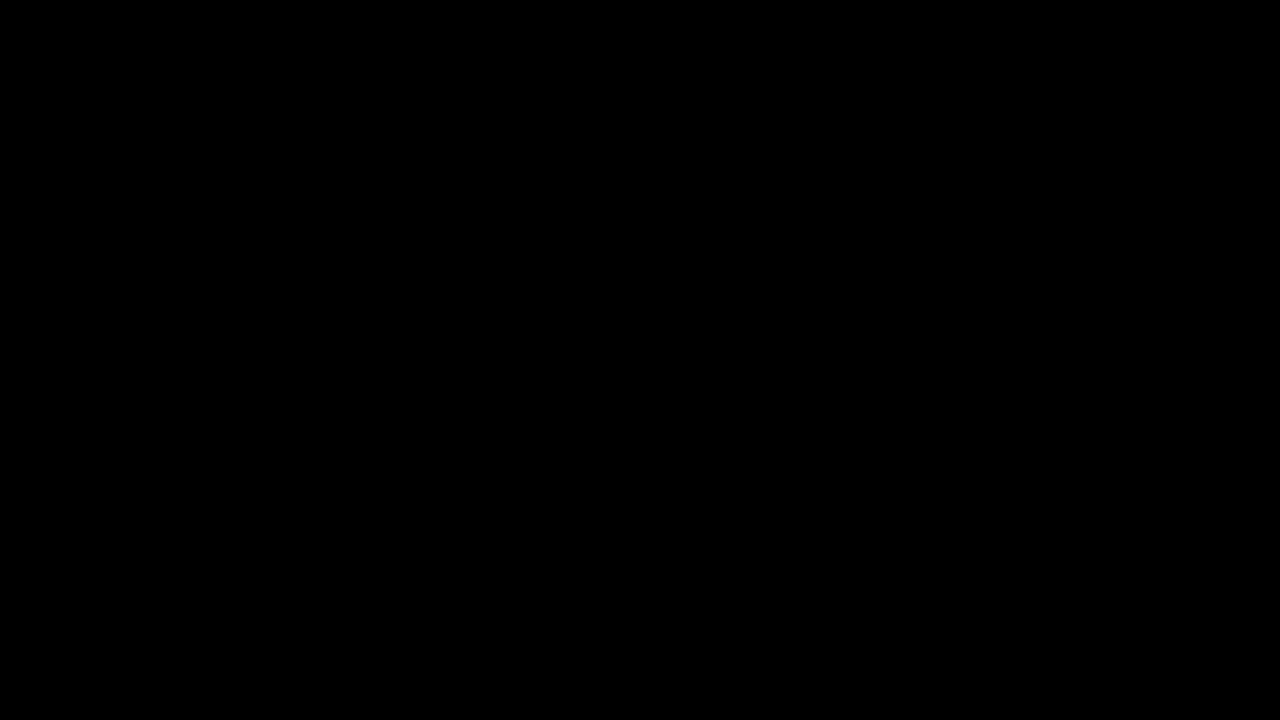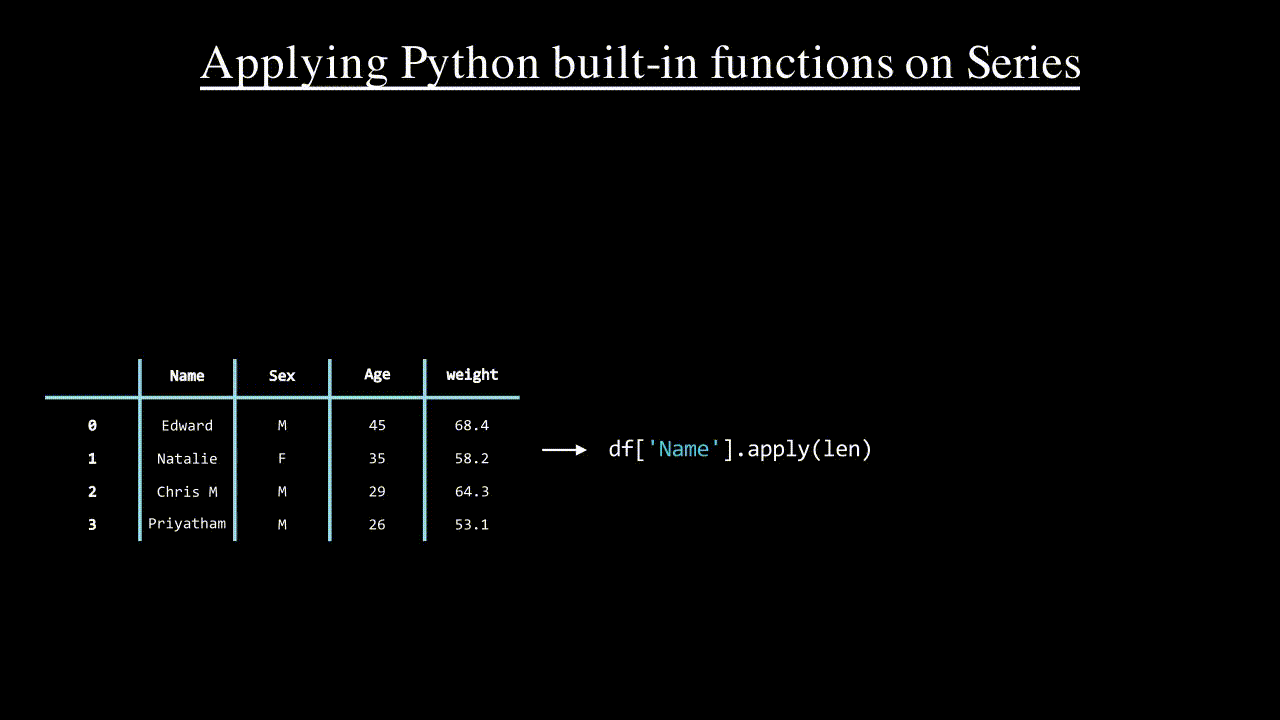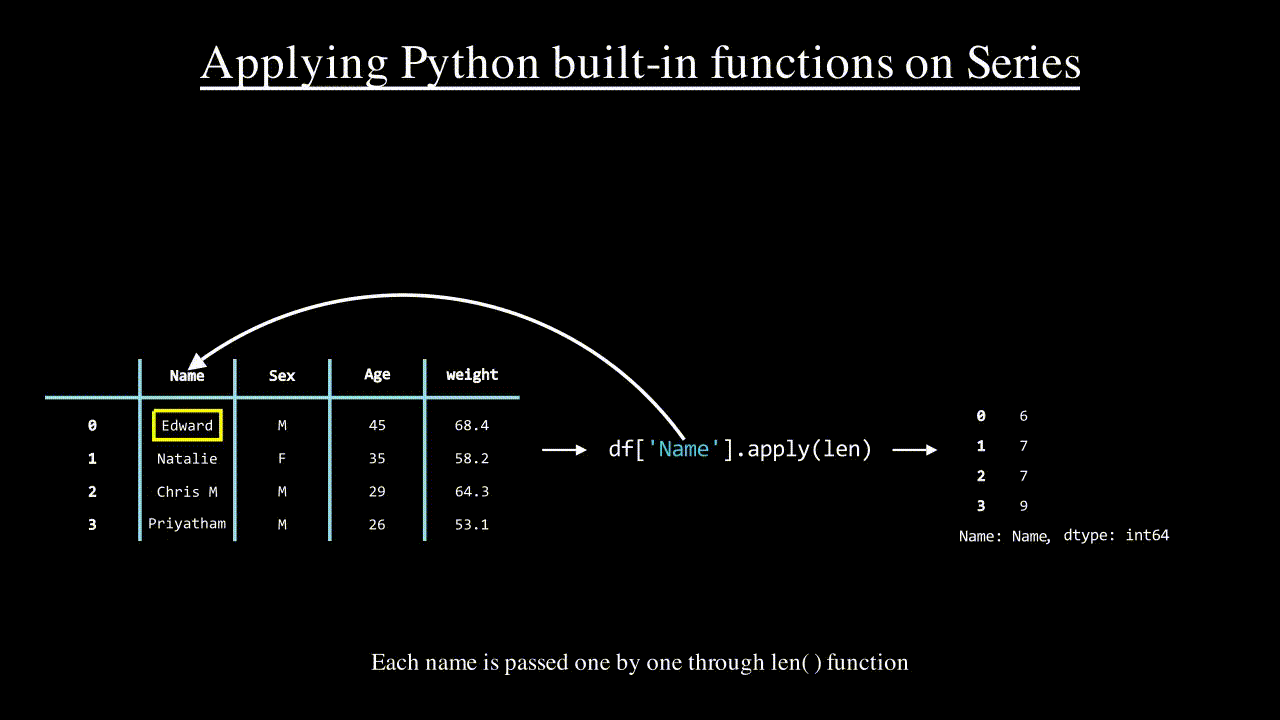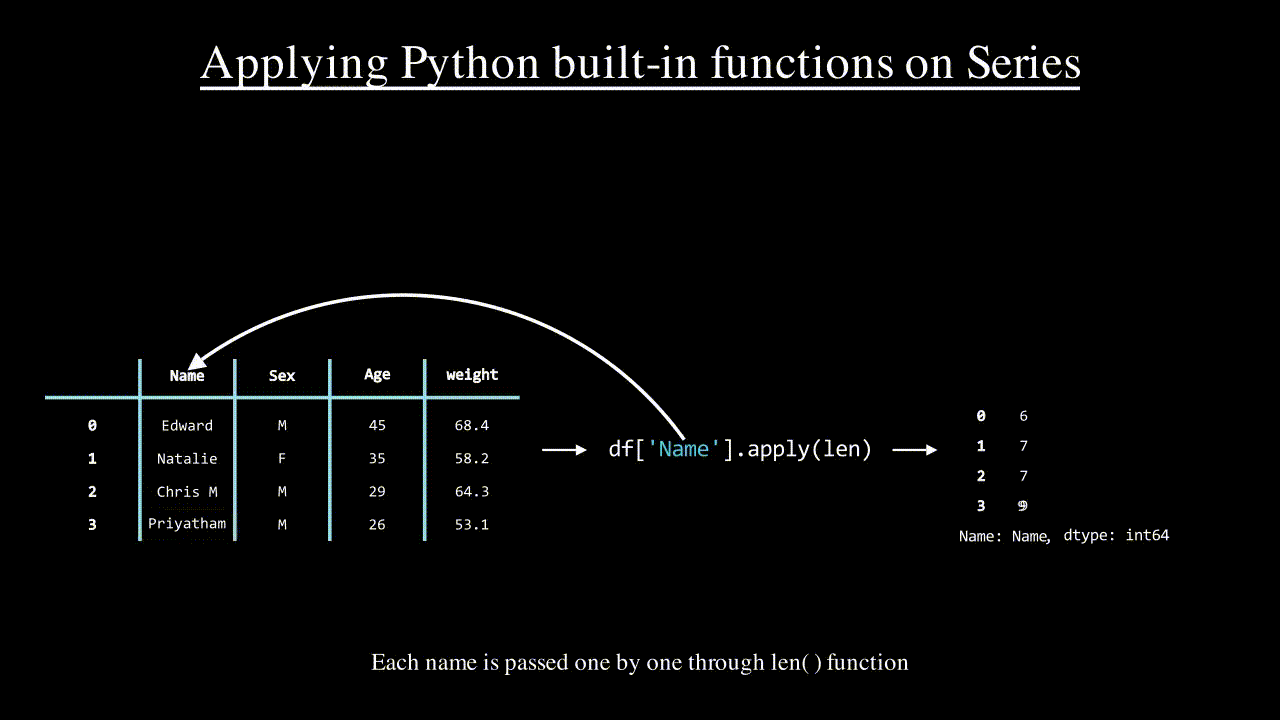
In the above visualisation, you can observe that each element of Series is applied to the function one by one.
b) Applying user-defined functions on Series
Let’s assume that the data we have is a year old. So, we would like to update the age of each person by adding 1. We can do so by applying a user-defined function on the Series object using the method.
The code for it is,
From the above result, the major point to be noted is,
It operates in the same way as applying built-in functions. Each element in the Series is passed one by one to the function.
c) Applying Lambda functions on Series
Lambda functions are used a lot along with themethod. We used a user-defined function for an easy addition operation in the above section. Let’s achieve the same result using a Lambda function.
The code for it is,
From the above result, you can observe the results of applying the user-defined function and Lambda function are the same.
2. Numpy’s universal functions (ufuncs)
Numpyhas so many built-in universal functions (ufuncs). We can provide any of the ufuncs as an argument to the method on Series. A series object can be thought of as a NumPy array.
The difference between applying Python functions and ufuncs is;
Let’s choose to use a ufunc to floor the floating-point values of the weight column. We have ufunc to achieve this.
The code for it is,
In the above result, you can observe the floored to the nearest lower decimal point value and maintain its float64 data type.
We can visualise the above process as:
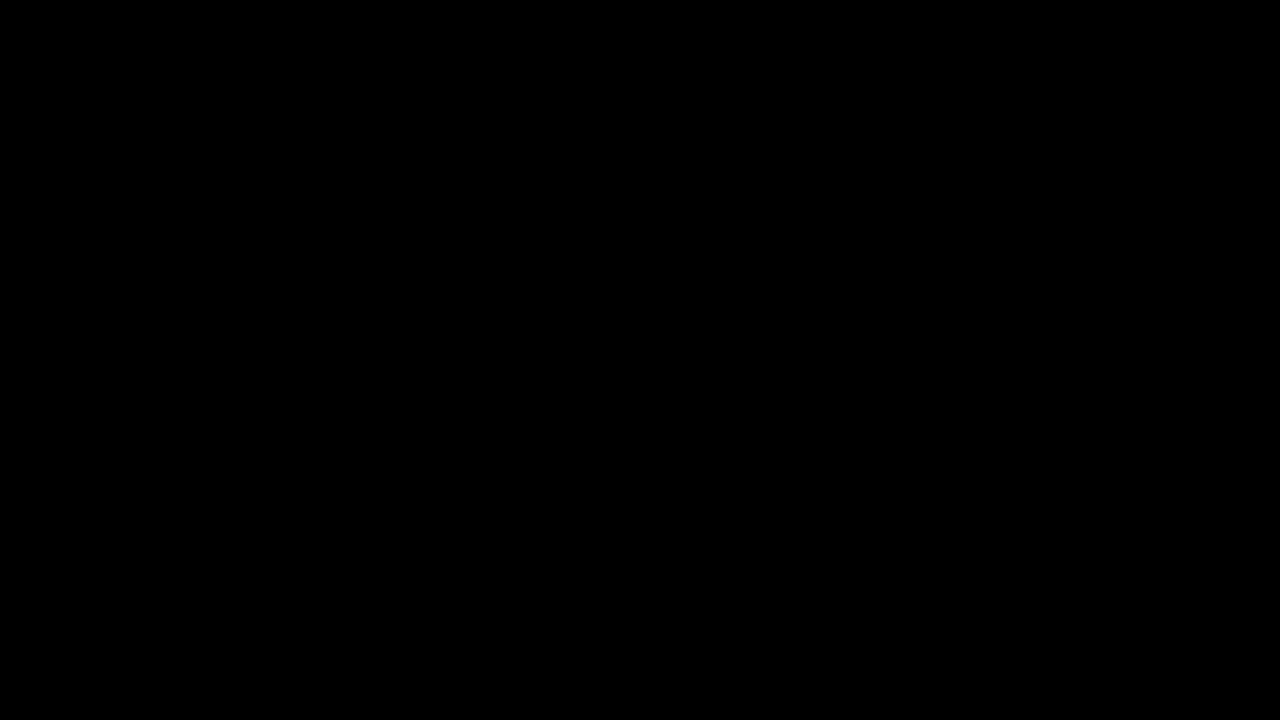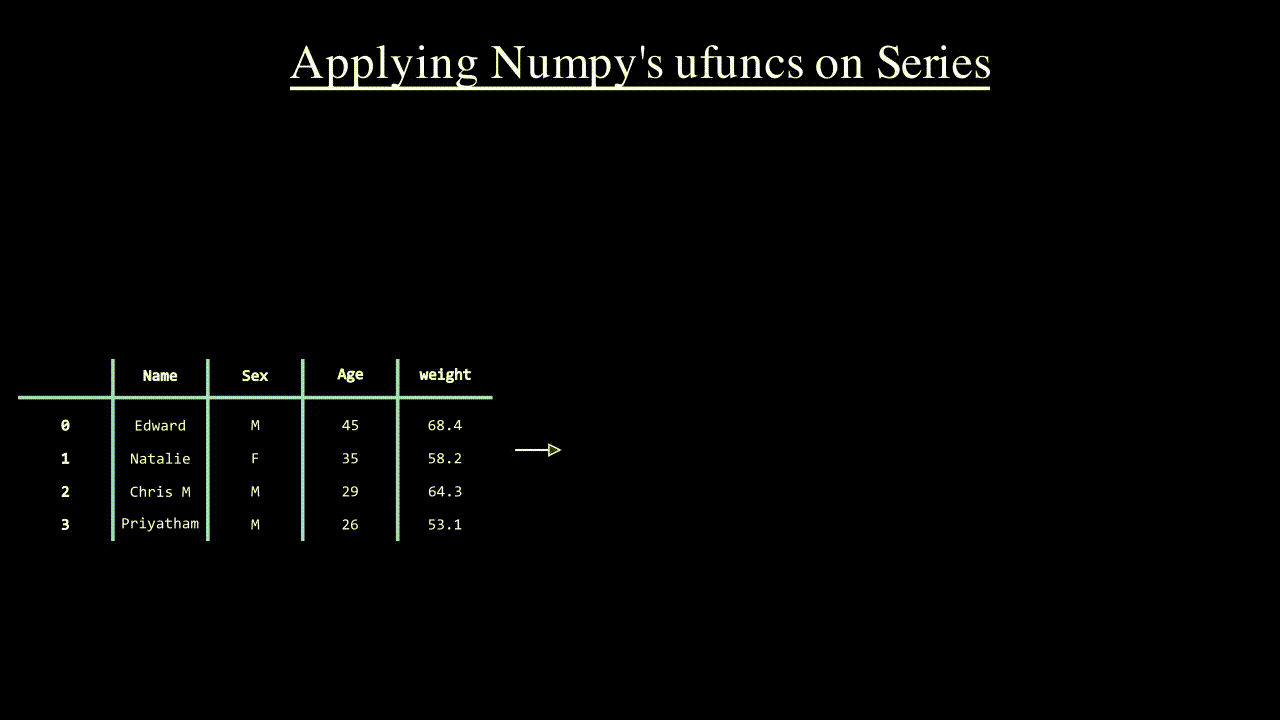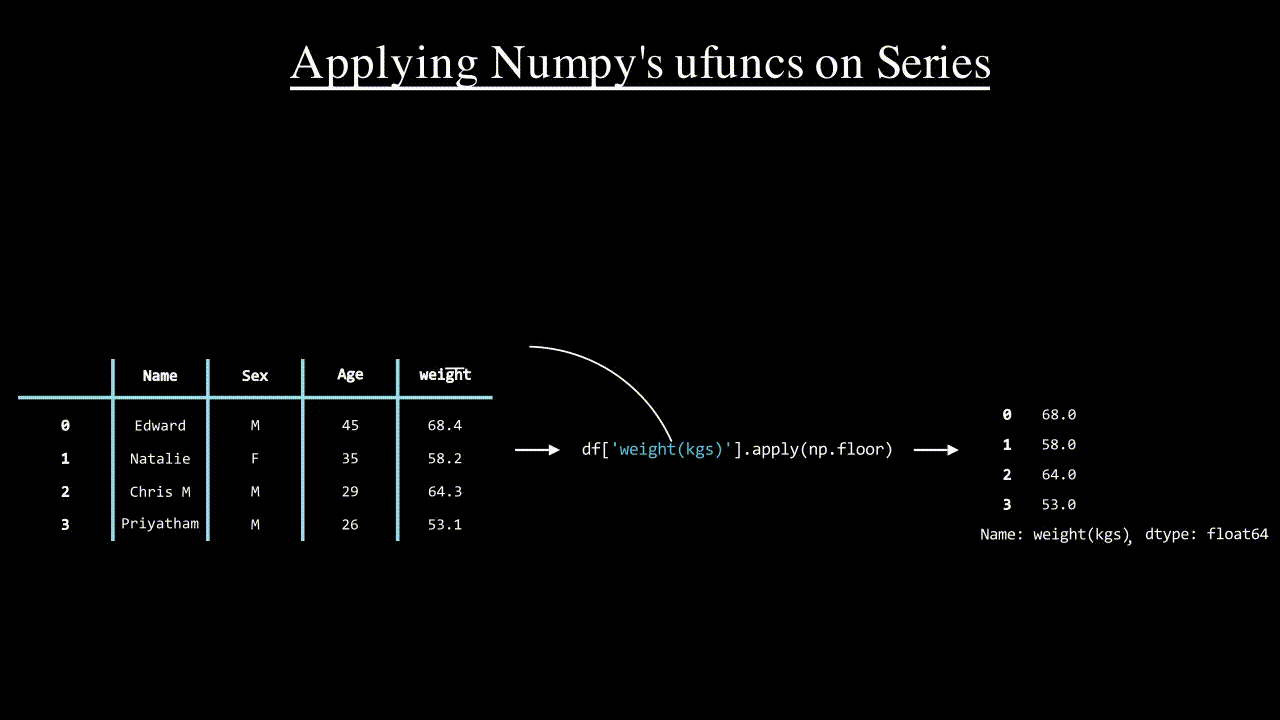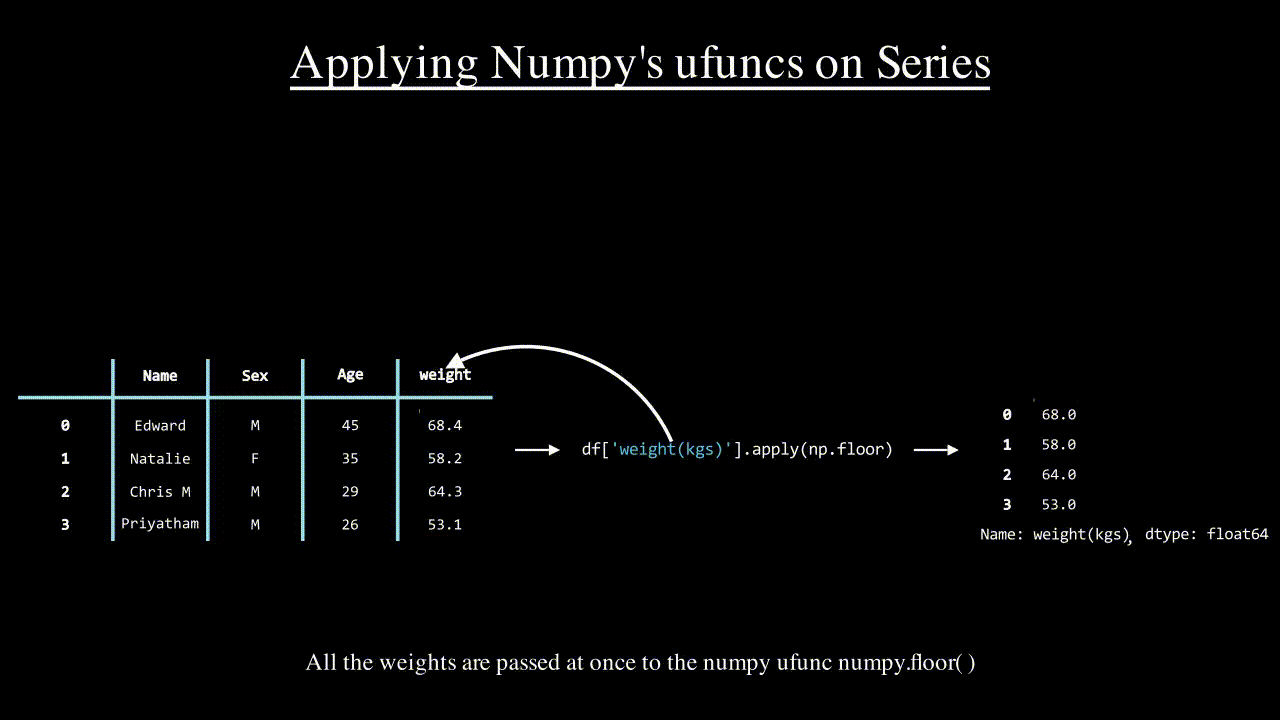
In the above visualisation, you can observe that all elements of Series are applied to the function at once.
Pandas apply( ) as a DataFrame method
We will take a look at the official documentation of the method on DataFrame:

has two important arguments;
Again the axis also has 2 possible values;
1. Pandas apply function to multiple columns
Let’s say the people in our dataset provided their height (in cms) information. It can be added using the following code,
We’ll make the “Name” column the index of the DataFrame. Also, we’ll get the subset of the DataFrame with “Age”, “weight(kgs)”, and “height(cms)” columns.
If we would like to get the average age, weight, and height of all the people, we can use the numpy .
The code for it is,
We directly have a Pandas DataFrame aggregation function called which does the same as above;
If you observe the results above, the results of Pandas DataFrame aggregation function and applying are equal. So, we don’t use the method in such simple scenarios where we have aggregation functions available.
2. Pandas apply function to every row
Based upon the height and weight, we can know whether they’re fit or thin, or obese. The fitness criteria are different for men and women as setup by international standards. Let’s grab the fitness criteria data for the heights and weights of the people in our data.
This can be represented using a dictionary;
In the above dictionary, the keys are the heights and the values are tuples of the lower and upper limit of ideal weight respectively.
If someone is below the ideal weight for their respective height, they are “Thin”. If someone is above the ideal weight for their respective height, they are “Obese”. If someone is in the range of ideal weight for their respective height, they are “Fit”.
Let’s build a function that can be used in the method that takes all the rows one by one.
The function returns whether a given person is “Fit” or “Thin” or “Obese”. It uses the different fitness criteria dictionaries for male and female created above.
Finally, let’s apply the above function to every row using the method;
From the above result, we got to know who is Fit or Thin or Obese.
Conclusion and Next Steps
Using the method when you want to achieve some complex functionality is preferred and recommended. Mostly built-in aggregation functions in Pandas come in handy. If you liked this tutorial on the function and like quiz-based learning, please consider giving it a try to read our Coffee Break Pandas book.
The post Pandas apply() — A Helpful Illustrated Guide first appeared on Finxter.
The Pandas
Code:
apply( )Code:
apply( )Code:
apply( )Pandas apply function to one column – apply( ) as Series method
Let’s construct a DataFrame in which we have the information of 4 persons.
Code:
>>> import pandas as pd
>>> df = pd.DataFrame(
... {
... 'Name': ['Edward', 'Natalie', 'Chris M', 'Priyatham'],
... 'Sex' : ['M', 'F', 'M', 'M'],
... 'Age': [45, 35, 29, 26],
... 'weight(kgs)': [68.4, 58.2, 64.3, 53.1]
... }
... ) >>> print(df) Name Sex Age weight(kgs)
0 Edward M 45 68.4
1 Natalie F 35 58.2
2 Chris M M 29 64.3
3 Priyatham M 26 53.1
Code:
pandas.Series.apply- Python functions
- Numpy’s universal functions (ufuncs)
1. Python functions
In Python, there are 3 different kinds of functions in general;
- Built-in functions
- User-defined functions
- Lambda functions
a) Applying Python built-in functions on Series
If we would like to know the length of the names of each person, we can do so using the
Code:
len( )For example, if we want to know the length of the “Python” string, we can get by the following code;
Code:
>>> len("Python")
6
A single column in the DataFrame is a Series object. Now, we would like to apply the same
Code:
len( )Code:
apply( )Code:
>>> df['Name'].apply(len)
0 6
1 7
2 7
3 9
Name: Name, dtype: int64
If you observe the above code snippet, the
Code:
lenCode:
apply( )Code:
len(“Python”)Code:
“Python”Code:
apply( )When applying the Python functions, each value in the Series is applied one by one and returns the Series object.
The above process can be visualised as:
In the above visualisation, you can observe that each element of Series is applied to the function one by one.
b) Applying user-defined functions on Series
Let’s assume that the data we have is a year old. So, we would like to update the age of each person by adding 1. We can do so by applying a user-defined function on the Series object using the
Code:
apply( )The code for it is,
Code:
>>> def add_age(age):
... return age + 1 >>> df['Age'].apply(add_age)
0 46
1 36
2 30
3 27
Name: Age, dtype: int64 >>> df['Age'] = df['Age'].apply(add_age) >>> df Name Sex Age weight(kgs)
0 Edward M 46 68.4
1 Natalie F 36 58.2
2 Chris M M 30 64.3
3 Priyatham M 27 53.1
From the above result, the major point to be noted is,
- The index of the resultant Seriesis equal to the index of the caller Series object. This makes the process of adding the resultant Series as a column to the DataFrame easier.
It operates in the same way as applying built-in functions. Each element in the Series is passed one by one to the function.
- User-defined functions are used majorly when we would like to apply some application-specific complex functions.
c) Applying Lambda functions on Series
Lambda functions are used a lot along with the
Code:
apply( )The code for it is,
Code:
>>> df['Age'].apply(lambda x: x+1)
0 46
1 36
2 30
3 27
Name: Age, dtype: int64 >>> # Comparing the results of applying both the user-defined function and Lambda function
>>> df['Age'].apply(lambda x: x+1) == df['Age'].apply(add_age)
0 True
1 True
2 True
3 True
Name: Age, dtype: bool
From the above result, you can observe the results of applying the user-defined function and Lambda function are the same.
- Lambda functions are used majorly when we would like to apply some application-specific small functions.
2. Numpy’s universal functions (ufuncs)
Numpyhas so many built-in universal functions (ufuncs). We can provide any of the ufuncs as an argument to the
Code:
apply( )The difference between applying Python functions and ufuncs is;
- When applying the Python Functions, each element in the Series is operated one by one.
- When applying the ufuncs, the entire Series is operated at once.
Let’s choose to use a ufunc to floor the floating-point values of the weight column. We have
Code:
numpy.floor( )The code for it is,
Code:
>>> import numpy as np >>> df['weight(kgs)']
0 68.4
1 58.2
2 64.3
3 53.1
Name: weight(kgs), dtype: float64 >>> df['weight(kgs)'].apply(np.floor)
0 68.0
1 58.0
2 64.0
3 53.0
Name: weight(kgs), dtype: float64
In the above result, you can observe the floored to the nearest lower decimal point value and maintain its float64 data type.
We can visualise the above process as:
In the above visualisation, you can observe that all elements of Series are applied to the function at once.
- Whenever we have a to achieve our functionality, we can use it instead of defining a Python function.Code:
ufunc
Pandas apply( ) as a DataFrame method
We will take a look at the official documentation of the
Code:
apply( )Code:
pandas.DataFrame.apply- – Function to be applied along the mentioned axisCode:
func
- – Axis along which function is appliedCode:
axis
Again the axis also has 2 possible values;
- – Apply function to multiple columnsCode:
axis=0
- – Apply function to every rowCode:
axis=1
1. Pandas apply function to multiple columns
Let’s say the people in our dataset provided their height (in cms) information. It can be added using the following code,
Code:
>>> df['height(cms)'] = [178, 160, 173, 168]
>>> df Name Sex Age weight(kgs) height(cms)
0 Edward M 45 68.4 178
1 Natalie F 35 58.2 160
2 Chris M M 29 64.3 173
3 Priyatham M 26 53.1 168
We’ll make the “Name” column the index of the DataFrame. Also, we’ll get the subset of the DataFrame with “Age”, “weight(kgs)”, and “height(cms)” columns.
Code:
>>> data = df.set_index('Name')
>>> data Sex Age weight(kgs) height(cms)
Name Edward M 45 68.4 178
Natalie F 35 58.2 160
Chris M M 29 64.3 173
Priyatham M 26 53.1 168 >>> data_subset = data[['Age', 'weight(kgs)', 'height(cms)']]
>>> data_subset Age weight(kgs) height(cms)
Name Edward 45 68.4 178
Natalie 35 58.2 160
Chris M 29 64.3 173
Priyatham 26 53.1 168
If we would like to get the average age, weight, and height of all the people, we can use the numpy
Code:
ufuncCode:
numpy.mean( )The code for it is,
Code:
>>> import numpy as np
>>> data_subset.apply(np.mean, axis=0)
Age 33.75
weight(kgs) 61.00
height(cms) 169.75
dtype: float64
We directly have a Pandas DataFrame aggregation function called
Code:
mean( )Code:
>>> data_subset.mean()
Age 33.75
weight(kgs) 61.00
height(cms) 169.75
dtype: float64
If you observe the results above, the results of Pandas DataFrame aggregation function and applying
Code:
ufuncCode:
apply( )- Whenever you have to apply some complex functions on DataFrames, then use the method.Code:
apply( )
2. Pandas apply function to every row
Based upon the height and weight, we can know whether they’re fit or thin, or obese. The fitness criteria are different for men and women as setup by international standards. Let’s grab the fitness criteria data for the heights and weights of the people in our data.
This can be represented using a dictionary;
Code:
>>> male_fitness = {
... #height : (weight_lower_cap, weight_upper_cap)
... 178 : ( 67.5 , 83 ),
... 173 : ( 63 , 70.6 ),
... 168 : ( 58 , 70.7 )
... }
>>> female_fitness = {
... #height : (weight_lower_cap, weight_upper_cap)
... 160 : ( 47.2 , 57.6 )
... }
In the above dictionary, the keys are the heights and the values are tuples of the lower and upper limit of ideal weight respectively.
If someone is below the ideal weight for their respective height, they are “Thin”. If someone is above the ideal weight for their respective height, they are “Obese”. If someone is in the range of ideal weight for their respective height, they are “Fit”.
Let’s build a function that can be used in the
Code:
apply( )Code:
>>> def fitness_check(seq):
... if seq.loc['Sex'] == 'M':
... if (seq.loc['weight(kgs)'] > male_fitness[seq.loc['height(cms)']][0]) & (seq.loc['weight(kgs)'] < male_fitness[seq.loc['height(cms)']][1]):
... return "Fit"
... elif (seq.loc['weight(kgs)'] < male_fitness[seq.loc['height(cms)']][0]):
... return "Thin"
... else:
... return "Obese"
... else:
... if (seq.loc['weight(kgs)'] > female_fitness[seq.loc['height(cms)']][0]) & (seq.loc['weight(kgs)'] < female_fitness[seq.loc['height(cms)']][1]):
... return "Fit"
... elif (seq.loc['weight(kgs)'] < female_fitness[seq.loc['height(cms)']][0]):
... return "Thin"
... else:
... return "Obese"
The function returns whether a given person is “Fit” or “Thin” or “Obese”. It uses the different fitness criteria dictionaries for male and female created above.
Finally, let’s apply the above function to every row using the
Code:
apply( )Code:
>>> data.apply(fitness_check, axis=1)
Name
Edward Fit
Natalie Obese
Chris M Fit
Priyatham Thin
dtype: object
From the above result, we got to know who is Fit or Thin or Obese.
Conclusion and Next Steps
Using the
Code:
apply( )Code:
apply( )The post Pandas apply() — A Helpful Illustrated Guide first appeared on Finxter.