+- Sick Gaming (https://sickgaming.net)
+-- Forum: Programming (https://sickgaming.net/forum-76.html)
+--- Forum: Python (https://sickgaming.net/forum-83.html)
+--- Thread: [Py Blog] Memory Buffer Protocol (Python Language Summit 2026) (/thread-113513.html)
[Py Blog] Memory Buffer Protocol (Python Language Summit 2026) - xSicKxBot - 09-30-2026
The Python Buffer Protocol defines the semantics for accessing the underlying memory buffer of Python objects such as
Code:
bytesCode:
bytearrayCode:
array.array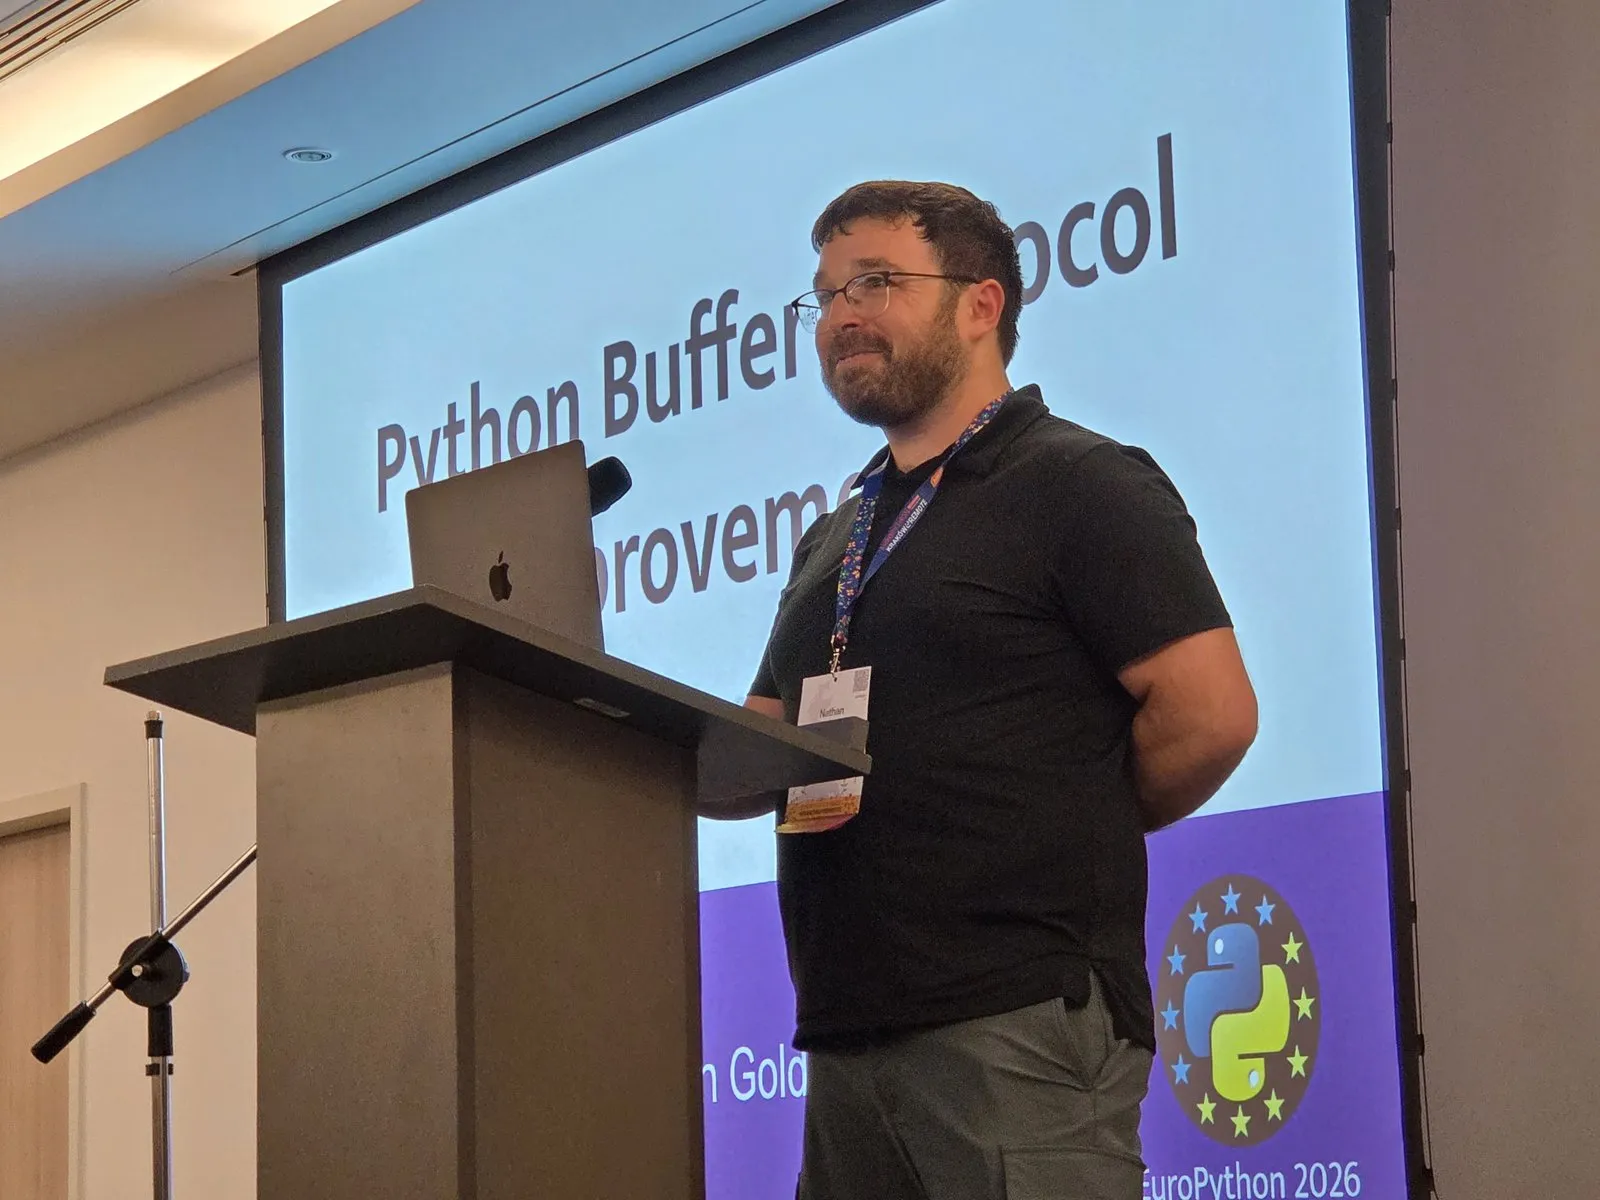
Photo by Hugo van Kemenade (CC BY-NC-SA 4.0)
Documenting the Buffer Protocol
Nathan Goldbaum opened with some suggestions that were unlikely to be controversial, like improving the documentation and making the Buffer Protocol specification less fragmented. Buffers support a “struct-style” language that is similar to, but much more featureful than, Python’s struct format strings. “There are corners of the format language that are underspecified”.
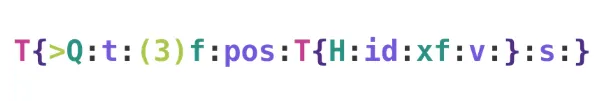
Today, users are expected to read PEP 3118 or implementations like NumPy to understand the full grammar, “including records, field names, subarrays, byte order, alignment, and complex numbers”. Documenting all features within the Python documentation would be a meaningful improvement.
Continuing with helping consumers of the Buffer Protocol, Nathan proposed creating a HOWTO guide for exporters and consumers of the Buffer Protocol, citing a lack of “complete examples” in C that implement validation, cleanup, ownership, and safe use of threads.
Safe concurrency
Nathan was primarily looking for feedback on the upcoming sections of the talk, for which there are drafted PEPs addressing two shortcomings of the Buffer Protocol: coordinating concurrent reads and writes and custom data types.
The first issue was that the Python Buffer Protocol “didn’t support read and write coordination at the protocol level”. Storage addresses were stable, but contents were not. The Buffer Protocol supports a
Code:
readonlyNathan’s proposal to add safe coordination of reads and writes was through new buffer “leasing” C APIs,
Code:
PyBufferLeaseCode:
PyBufferAccessStateCode:
[code]PyBufferLease *lease = PyObject_AcquireBufferLease(obj,
                                                   PyBUF_CONTIG_RO,
                                                   Py_BUFFER_ACCESS_SHARED_READ);

if (lease == NULL) {
    return -1;
}

const Py_buffer *view = PyBufferLease_GetView(lease);

Py_BEGIN_ALLOW_THREADS
consume_bytes(view->buf, view->len);
Py_END_ALLOW_THREADS

PyBufferLease_Release(lease);[/code]
Leases could be opened in either
Code:
SHARED_READCode:
EXCLUSIVE_WRITECode:
PyObject_AcquireBufferLease()Code:
EXCLUSIVE_WRITE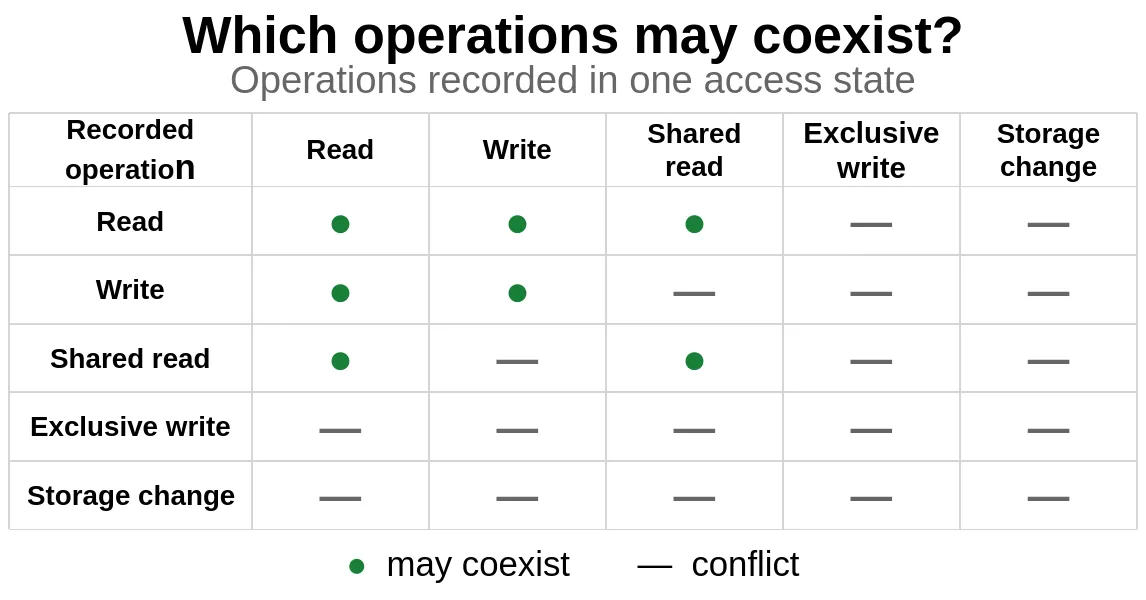
The existing PyObject_GetBuffer(), PyBuffer_Release(), and other related interfaces would remain unchanged under Nathan’s proposal. Buffer exporters would advertise explicit support for the new access modes, and exporters that don’t support the new access APIs would continue to use existing APIs as-is. Consumers would query the exporter using
Code:
PyObject_GetBufferAccessModes()There is already an implementation being worked on that is similar to this proposal. Kumar Aditya is working on changes to NumPy allowing interoperability with the PEP, but Nathan noted that NumPy allowing access to raw pointers presented an “interesting” challenge.
Nathan published his PEP draft, is requesting feedback, and will open a PEP discussion soon.
Custom Data Types
Finally, Nathan detailed a proposal that he and Sebastian Berg created that would add an extension point to the Buffer Protocol for custom data types. Today the Buffer Protocol format has a “fixed vocabulary”, meaning that to support custom data types, third parties either need to land a new type and format code in Python or use “out-of-band signaling and convention”. Instead of needing to block new types and format codes on a decision from the Python Steering Council, a namespace-based approach to custom data types could be used.
In this proposed extension, a custom data type would be defined with square brackets (
Code:
[]Code:
$Nathan pointed to a discussion on discuss.python.org and the draft PEP for this proposal.
Discussion
Photo by EuroPython (CC BY-NC-SA 4.0)
Petr Viktorin asked whether a new API was needed for this proposal or whether the existing
Code:
PyObject_GetBuffer()Thomas Wouters asked how Nathan’s proposal compares to Rust: when asking for exclusive write access, should the request block or error out? Nathan replied that erroring out would be the simplest implementation. David Hewitt asked about the composability of the implementation, and whether it could accommodate additional, likely desirable features like “blocking, asynchronously blocking, or more complicated structures like writing to slices”.
Larry Hastings wondered whether this new API assumes that users are being diligent and using the API correctly. Nathan confirmed that memory corruption would be possible if the APIs were used incorrectly, but that pure-Python users wouldn’t be able to do this, only authors of C extensions. Leaking memory wouldn’t be possible.
Photo by Hugo van Kemenade (CC BY-NC-SA 4.0)
Hood Chatham asked whether buffer exporters would be allowed to reject consumers using the old buffer access pattern without specifying either
Code:
SHARED_READCode:
EXCLUSIVE_WRITE