
+- Sick Gaming (https://sickgaming.net)
+-- Forum: Programming (https://sickgaming.net/forum-76.html)
+--- Forum: Python (https://sickgaming.net/forum-83.html)
+--- Thread: [Tut] How to Filter Data from an Excel File in Python with Pandas (/thread-100165.html)
[Tut] How to Filter Data from an Excel File in Python with Pandas - xSicKxBot - 10-31-2022
How to Filter Data from an Excel File in Python with Pandas
5/5 – (1 vote)
Problem Formulation and Solution Overview
This article will show different ways to read and filter an Excel file in Python.
To make it more interesting, we have the following scenario:
Sven is a Senior Coder at K-Paddles. K-Paddles manufactures Kayak Paddles made of Kevlar for the White Water Rafting Community. Sven has been asked to read an Excel file and run reports. This Excel file contains two (2) worksheets, Employees and Sales.

To follow along, download the
Code:
kp_data.xlsx Question: How would we write code to filter an Excel file in Python?
We can accomplish this task by one of the following options:
- Method 1: Use and theCode:
read_excel()operatorCode:&
- Method 2: Use andCode:
read_excel()Code:loc[]
- Method 3: Use andCode:
read_excel()Code:iloc[]
- Method 4: Use ,Code:
read_excel()andCode:index[]Code:loc[]
- Method 5: Use andCode:
read_excel()Code:isin()
Method 1: Use read_excel() and the & operator
This method uses the
Code:
read_excel()This example imports the above-noted Excel file into a DataFrame. The
Code:
Employees Give me the DataFrame rows for all employees who work in the Sales Department, and earn more than $55,000/annum.
Let’s convert this to Python code.
Code:
import pandas as pd cols = ['First', 'Last', 'Dept', 'Salary']
df_emps = pd.read_excel('kp_data.xlsx', sheet_name='Employees', usecols=cols)
df_salary = df_emps[(df_emps['Dept'] == 'Sales') & (df_emps['Salary'] > 55000)] df_salary.to_excel('sales_55.xlsx', sheet_name='Sales Salaries Greater Than 55K')
The first line in the above code snippet imports the Pandas library. This allows access to and manipulation of the XLSX file. Just so you know, the
Code:
openpyxlThe following line defines the four (4) columns to retrieve from the XLSX file and saves them to the variable
Code:
cols Note: Open the Excel file and review the data to follow along.
Import the Excel File to Python
On the next line in the code snippet,
Code:
read_excel()- The name of the Excel file to import ().Code:
kp_data.xlsx
- The worksheet name. The first worksheet in the Excel file is always read unless stated otherwise. For this example, our Excel file contains two (2) worksheets: andCode:
Employees. The Employees worksheet can be referenced usingCode:SalesorCode:sheet_name=0. Both produce the same result.Code:sheet_name='Employees'
- The columns to retrieve from the Excel workheet ().Code:
usecols=cols
The results save to
Code:
df_empsFilter the DataFrame
The highlighted line applies a filter that references the DataFrame columns to base the filter on and the
Code:
&In Python, this filter:
Code:
df_salary = df_emps[(df_emps['Dept'] == 'Sales') & (df_emps['Salary'] > 55000)]Equates to this:
Give me the DataFrame rows for all employees who work in the Sales Department, and earn more than $55,000/annum.These results save to
Code:
sales_55.xlsxCode:
Sales Salaries Greater Than 55KContents of Filtered Excel File


Method 2: Use read_excel() and loc[]
This method uses the
Code:
read_excel()Code:
loc[]Code:
loc[]This example imports the above-noted Excel file into a DataFrame. The
Code:
Employees Give me the DataFrame rows for all employees who work in the IT Department, and live in the United States.Let’s convert this to Python code.
Code:
import pandas as pd
from openpyxl import load_workbook cols = ['First', 'Last', 'Dept', 'Country']
df_emps = pd.read_excel('kp_data.xlsx', sheet_name='Employees', usecols=cols)
df_it = df_emps.loc[(df_emps.Dept == 'IT') & (df_emps.Country == 'United States')] book = load_workbook('kp_data.xlsx')
writer = pd.ExcelWriter('kp_data.xlsx', engine='openpyxl')
writer.book = book
df_it.to_excel(writer, sheet_name = 'IT - US')
writer.save()
writer.close()
The first line in the above code snippet imports the Pandas library. This allows access to and manipulation of the XLSX file. Just so you know, the
Code:
openpyxlThe following line imports
Code:
openpyxlThe following line defines the four (4) columns to retrieve from the XLSX file and saves them to the variable
Code:
colsCode:
ListNote: Open the Excel file and review the data to follow along.Import the Excel File to Python
On the next line in the code snippet,
Code:
read_excel()- The name of the Excel file to import ().Code:
kp_data.xlsx
- The worksheet name. The first worksheet in the Excel file is always read unless stated otherwise. For this example, our Excel file contains two (2) worksheets: andCode:
Employees. The Employees worksheet can be referenced usingCode:SalesorCode:sheet_name=0. Both produce the same result.Code:sheet_name='Employees'
- The columns to retrieve from the Excel worksheet ().Code:
usecols=cols
The results save to
Code:
df_itFilter the DataFrame
The highlighted line applies a filter using
Code:
loc[]In Python, this filter:
Code:
df_it = df_emps.loc[(df_emps.Dept == 'IT') & (df_emps.Country == 'United States')]Equates to this:
Give me the DataFrame rows for all employees who work in the IT Department, and live in the United States.Saves Results to Worksheet in Same Excel File
In the bottom highlighted section of the above code, the Excel file is re-opened using
Code:
load_workbook()Code:
IT - US

Method 3: Use read_excel() and iloc[]
This method uses the
Code:
read_excel()Code:
iloc[]Code:
iloc[]This example imports required
Code:
PandasCode:
SalesThis worksheet contains the yearly sale totals for K-Paddles paddles. These results are filtered to the first six (6) rows in the DataFrame and columns shown below.
Code:
import pandas as pd cols = ['Month', 'Aspire', 'Adventurer', 'Maximizer']
df_sales = pd.read_excel('kp_data.xlsx', sheet_name='Sales', usecols=cols)
df_aspire = df_sales.iloc[0:6]
print(df_aspire)
The results are output to the terminal.
|
Month |
Aspire |
Adventurer |
Maximizer
0 |
1 |
2500 |
5200 |
21100
1 |
2 |
2630 |
5100 |
18330
2 |
3 |
2140 |
4550 |
22470
3 |
4 |
3400 |
5870 |
22270
4 |
5 |
3600 |
4560 |
20960
5 |
6 |
2760 |
4890 |
20140
Method 4: Use read_excel(), index[] and loc[]
This method uses the
Code:
read_excel()Code:
index[]Code:
loc[]Code:
loc[]This example imports the required
Code:
PandasCode:
SalesThese results are filtered to view the results for the Pinnacle paddle using
Code:
index[]Code:
import pandas as pd cols = ['Month', 'Pinnacle']
df_pinnacle = pd.read_excel('kp_data.xlsx', sheet_name='Sales', usecols=cols)
print(df_pinnacle.loc[df_pinnacle.index[0:5], ['Month', 'Pinnacle']])
The results are output to the terminal.
|
Month |
Pinnacle
0 |
1 |
1500
1 |
2 |
1200
2 |
3 |
1340
3 |
4 |
1130
4 |
5 |
1740

Method 5: Use read_excel() and isin()
This method uses the
Code:
read_excel()Code:
isin()Code:
isin()This example imports required
Code:
PandasCode:
EmployeesThese results are filtered to view the results for all employees who reside in Chicago.
Code:
import pandas as pd cols = ['First', 'Last', 'City']
df_emps = pd.read_excel('kp_data.xlsx', sheet_name='Employees', usecols=cols)
print(df_emps[df_emps.City.isin(['Chicago'])])
The results are output to the terminal.
|
First |
Last |
City
2 |
Luna |
Sanders |
Chicago
3 |
Penelope |
Jordan |
Chicago
9 |
Madeline |
Walker |
Chicago
34 |
Caroline |
Jenkins |
Chicago
Summary
This article has provided five (5) ways to filter data from an Excel file using Python to select the best fit for your coding requirements.
Good Luck & Happy Coding!
Programmer Humor – Blockchain
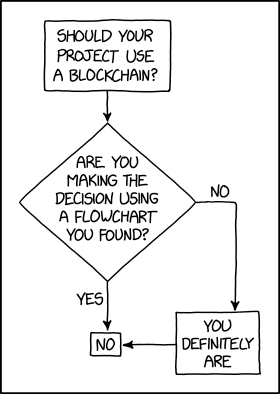 [i]“Blockchains are like grappling hooks, in that it’s extremely cool when you encounter a problem for which they’re the right solution, but it happens way too rarely in real life.” source – xkcd[/i]